How to Send Reddit Monitoring Data to Google Sheets Without Duplicate Rows

Getting Reddit data into a spreadsheet is easy once. Keeping the sheet correct after the tenth scheduled run is the real job. A useful monitoring sheet must answer four questions without making you reconstruct the workflow: 1. Is this post or comment already stored? 2. Which values changed since the last run? 3. Did every expected source complete? 4. Which rows still need a human decision? This guide builds a durable path from Reddit to BrowserAct, n8n, and Google Sheets. It uses one stable key
Start with the sheet, not the automation
Do not send raw results into an empty worksheet and invent columns while the workflow is running. Define the data contract first.
Use four tabs:
Tab | One row represents | Purpose |
| One monitoring target | Controls keywords, subreddits, URLs, limits, and enabled status |
| One canonical Reddit post or comment | Stores the latest known state of each item |
| One workflow execution | Proves whether collection was complete, partial, or failed |
| One unresolved data or editorial decision | Keeps uncertain timestamps, classifications, and access failures visible |
Runs tab supplies the missing coverage context.
Create a stable record key before writing a row
Use Reddit's item ID when it is available:
Post:    reddit:post:<post_id>
Comment: reddit:comment:<comment_id>
If an ID is unavailable, use a normalized canonical URL as the fallback. Remove tracking parameters and URL fragments before hashing it. Never use row number, collection time, title, score, or comment count as identity; all of those can change.
The key determines the write operation:
- no matching
record_key: append a new row; - matching
record_key: update only the mutable fields; - ambiguous identity: send the item to
Reviewand do not guess.
This is an upsert. n8n's current Google Sheets node supports both Append Row and Append or Update Row. For monitoring data, use Append or Update Row on Records; reserve plain append for immutable run logs.
Use a column schema that survives repeat runs
Create these columns in Records before connecting n8n:
Column | Rule |
| Required, unique match key |
| Native post or comment ID when visible |
|
|
| Required for comments |
| Direct source URL, stripped of tracking parameters |
| Community name without inventing a value |
| Post title; blank for a comment when not applicable |
| Visible source text |
| Visible author name or explicit unavailable value |
| Source publication time in UTC when reliable |
| Set once, never overwritten |
| Updated whenever the item is collected |
| Latest visible score; treat as mutable |
| Latest visible count; treat as mutable |
| All keywords or communities that matched the item |
| Deterministic or reviewed qualification result |
| Controlled label such as complaint or feature request |
| Controlled value: high, medium, or low |
| Evidence-based short description |
| Detects material text changes |
| Most recent run that touched the row |
|
|
first_seen_at_utc separate from published_at_utc. An old thread first discovered today is a new discovery, not a newly published post.
Build the Reddit collection in BrowserAct
BrowserAct's Reddit Intelligence Monitor is currently documented as an n8n workflow that reads keyword and competitor-subreddit configuration from Google Sheets, collects Reddit data with BrowserAct, cleans and formats the results, applies AI analysis, and archives structured output back to Google Sheets.
Use the template for the overall path. The prompt below makes the record identity and export contract explicit.
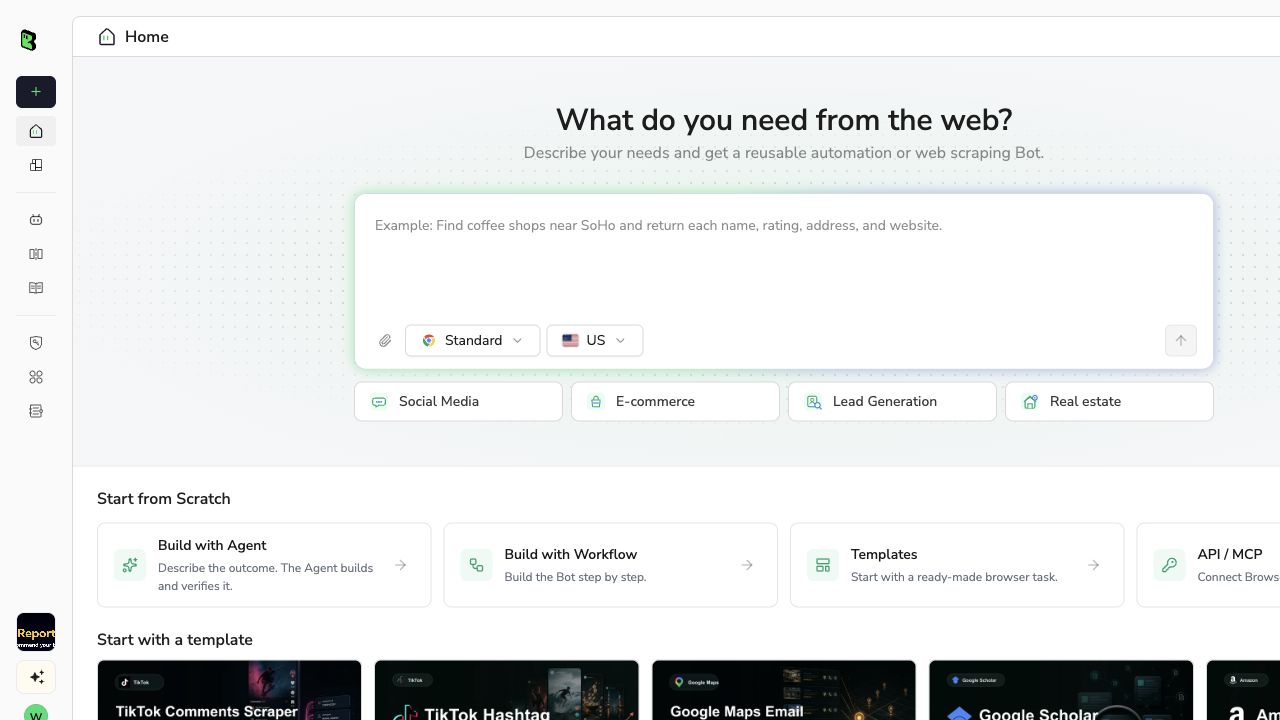
1. Open BrowserAct Dashboard
Open the BrowserAct Dashboard and click the left-side + to create a Bot. Paste the prompt into the Agent input. If you use the Reddit Intelligence Monitor template, open it and select Run task after replacing the example targets.
2. Copy the complete prompt
Replace the example targets and report window. Keep the field names unchanged so n8n can map them to Google Sheets reliably.
Create a reusable Bot that collects public Reddit posts and comments for a scheduled monitoring workflow and returns normalized, spreadsheet-ready JSON.

Inputs:
- run_id: reddit_sheet_2026-09-18T00-00Z
- collected_at_utc: 2026-09-18T00:00:00Z
- report_start_utc: 2026-09-17T00:00:00Z
- report_end_utc: 2026-09-18T00:00:00Z
- targets:
  - target_id: keyword_social_listening
    source_url: https://www.reddit.com/search/?q=%22social%20listening%22&sort=new
    item_type: post
    max_items: 50
  - target_id: community_saas
    source_url: https://www.reddit.com/r/SaaS/new/
    item_type: post
    max_items: 50
- previous_records: optional JSON containing record_key, first_seen_at_utc, content_hash, score, comment_count, and matched_targets from the last successful run

For every target independently:
1. Open the exact public source_url.
2. Validate that the expected Reddit search, subreddit, post, or comment view loaded.
3. Collect actual content items up to max_items.
4. Exclude ads, navigation, suggested communities, unrelated pinned announcements, and interface text.
5. Continue healthy targets if another target fails.

For every post, return:
- reddit_id when visible
- item_type: post
- parent_post_id: blank
- canonical_url
- subreddit
- title
- body when visible
- author when visible
- published_at_utc when reliable, otherwise published_time_raw
- score when visible
- comment_count when visible
- target_id
- run_id
- collected_at_utc

For every comment, return:
- reddit_id when visible
- item_type: comment
- parent_post_id
- canonical_url or permalink
- subreddit
- title: blank
- body
- author when visible
- published_at_utc when reliable, otherwise published_time_raw
- score when visible
- comment_count: blank
- target_id
- run_id
- collected_at_utc

Normalize each item:
- Build record_key as reddit:post:<reddit_id> or reddit:comment:<reddit_id>.
- If reddit_id is unavailable, normalize canonical_url by removing tracking parameters and fragments, then return record_key_source: canonical_url_fallback.
- Merge duplicate matches within this run and preserve all target_ids in matched_targets.
- Preserve first_seen_at_utc from previous_records when the record_key already exists; otherwise set it to collected_at_utc.
- Set last_seen_at_utc to collected_at_utc.
- Create content_hash from normalized title and body so material text changes can be detected.
- Never use title, score, comment count, row number, or collection time as the unique identity.

Return two arrays:
1. records: normalized canonical items ready for Google Sheets mapping;
2. source_health: one row per target with target_id, expected_url, final_url, rows_collected, health_status, and error_summary.

Return a third array named review for:
- missing or ambiguous identity;
- unreliable publication time;
- unexpected empty results;
- access blocks;
- records whose source view does not match the requested target.

Do not invent missing values. Do not write directly to Google Sheets. Do not join communities, vote, comment, message users, or change an account. If Reddit asks for login, CAPTCHA, 2FA, age confirmation, membership approval, or restricted access, pause that target and request manual handling.
Keep collection and storage separate. BrowserAct should return a validated record set; n8n decides whether each row is appended, updated, logged, or held for review.
Scrape data from any website. Describe the records you need and turn the task into a reusable Bot. Try: “Collect these Reddit sources, return one canonical record per item, and include source-health rows for the run.” Get your Bot — Free
3. Handle login only when asked
The workflow targets public or authorized pages. If Reddit requests login, CAPTCHA, 2FA, an age check, membership approval, or restricted access, complete that step manually only when authorized.
Mark the target as access_blocked or failed in the run log. Do not write an empty successful result to Google Sheets; that would make missing coverage look like no Reddit activity.
4. Review, dedupe, and export
Before connecting the live sheet:
- Inspect
records,source_health, andreviewseparately. - Confirm every record has a stable
record_keyor is routed to review. - Confirm one post matching several targets appears once with all match reasons.
- Confirm raw source text and canonical URLs are preserved.
- Export a small fixture containing a new item, an existing item with changed metrics, a duplicate match, and an ambiguous item.
Use that fixture for the n8n write test. Do not test the mapping only with clean new rows.
Connect BrowserAct to n8n
Build this node sequence:
Schedule Trigger
  → Google Sheets: Get Config Rows
  → Loop Over Enabled Targets
  → BrowserAct: Run Workflow
  → Normalize and Validate
  → Split: Records / Source Health / Review
  → Google Sheets writes
In the BrowserAct node:
- create the BrowserAct credential;
- select the published workflow or Bot;
- map the target, run ID, reporting window, and previous state;
- execute one target manually;
- inspect the output object before adding field expressions downstream.
Do not map columns from a remembered schema. Pin one real test output in n8n and map from the fields that are actually returned.
Configure the Google Sheets writes
Use a different operation for each tab.
Records: Append or Update Row
Select:
- resource: Sheet Within Document;
- operation: Append or Update Row;
- document: your monitoring spreadsheet;
- sheet:
Records; - matching column:
record_key.
Map fields manually. On an existing match:
- update
last_seen_at_utc, mutable metrics, labels,content_hash,run_id, andmatched_targets; - preserve
first_seen_at_utc; - preserve a manually approved classification unless your review policy explicitly reopens it;
- never blank an existing value just because the latest page omitted it.
Runs: Append Row
Append exactly one row after all target branches finish:
run_id
started_at_utc
ended_at_utc
expected_target_count
healthy_target_count
failed_target_count
records_received
records_inserted
records_updated
duplicates_merged
review_count
status
error_summary
Use complete, partial, or failed. The run row should be written even when no Reddit item qualified.
Review: Append or Update Row
Match on a composite review key such as:
<run_id>:<target_id>:<record_key-or-error-code>
Store the reason, source URL, raw value, proposed correction, owner, and resolution status. This stops unresolved items from disappearing into execution logs.
Protect the sheet from source text
Reddit titles and comments are untrusted text. A cell beginning with =, +, -, or @ can be interpreted as a formula depending on the write mode and spreadsheet behavior.
Before mapping user-controlled text:
- coerce the value to a string;
- remove disallowed control characters;
- prefix risky leading characters with an apostrophe or write them as raw/plain text;
- keep source URLs in their own column;
- never build formulas from collected text.
Apply this to titles, bodies, authors, summaries that contain quoted source text, and error messages.
Keep writes within quota and make retries safe
Google's current Sheets API documentation lists per-minute read and write quotas and recommends exponential backoff for 429 responses. It also recommends keeping request payloads around 2 MB or less for performance. See the current Google Sheets API limits.
For a monitoring workflow:
- normalize and deduplicate before writing;
- avoid a full-sheet lookup for every row when the upsert operation can match a key;
- batch where the node and workflow allow it;
- limit concurrent writes to one spreadsheet;
- retry quota and transient failures with backoff;
- reuse the same
run_idandrecord_keyon retry; - write the run as complete only after required row writes succeed.
A retry must be idempotent. If rerunning the same execution creates another copy of every post, the workflow is not ready for a schedule.
Test five cases before activation
Use a disposable copy of the spreadsheet and run these acceptance tests:
Test | Expected result |
New post | One new |
Same post, unchanged | Same row; only last-seen/run fields may change |
Same post, score or comment count changed | Existing row updated; first-seen preserved |
Same post found by two targets | One row with both target IDs |
One target fails | Healthy records remain; |
Also verify:
- a title beginning with
=remains visible text rather than a formula; - a blank optional field does not erase a valid stored value;
- an old item discovered today keeps its original publication time;
- every source URL opens the record it claims to represent;
- the run counts reconcile with inserted, updated, merged, and reviewed items.
Make the sheet useful for analysis
Once storage is reliable, add views instead of changing the source table:
- filter views for high urgency or pending review;
- a pivot by subreddit and category;
- a weekly count of new canonical items;
- a view of updated carryover conversations;
- a chart based only on complete runs;
- a lookup from summary evidence IDs back to canonical URLs.
Avoid placing complex formulas across the entire raw Records tab. Keep the archive stable and build analysis in a separate tab or connected reporting tool.
Final checklist
Before activating the Reddit-to-Sheets workflow, confirm that:
Config,Records,Runs, andReviewhave distinct purposes;- every post or comment has a stable record key;
Recordsuses append-or-update rather than blind append;- run logs are appended independently from content rows;
first_seen_at_utcis never overwritten;- mutable metrics can update without changing identity;
- duplicate matches merge before the sheet write;
- unsafe leading characters remain plain text;
- partial coverage cannot appear as a healthy zero-result run;
- retries reuse the same keys;
- a second identical run does not add duplicate record rows;
- every saved insight retains a canonical Reddit URL.
Frequently asked questions
Should I append every Reddit result to Google Sheets?
No. Append new canonical items, but update an existing row when the same post or comment returns. Blind append is appropriate for immutable run logs, not the current record table.
What should I use as the unique key?
Use Reddit's post or comment ID with an item-type prefix. Use a normalized canonical URL only as a fallback, and route ambiguous identities for review.
Can Google Sheets be the database for a Reddit monitor?
It works well for modest team workflows, review queues, and transparent analysis. As volume and concurrent writes grow, keep the same stable IDs and run logs so you can migrate the record store without changing collection semantics.
Why keep a Runs tab if the Records tab has timestamps?
Record timestamps show when items were seen. They do not prove that every expected source completed. The run log records coverage, failures, and reconciliation counts.
Should AI write directly into the sheet?
Write structured AI fields only after schema validation. Preserve the source text and URL, route low-confidence or high-impact classifications for review, and do not let generated prose replace the evidence record.


