How to Monitor Reddit Posts and Comments Without Losing Context

A Reddit post tells you what someone asked. The comments tell you what people tried, rejected, recommended, or argued about. If your monitoring workflow saves only post titles, it can find a conversation but still miss the useful part. This guide shows how to monitor public Reddit posts and their visible comments as one dataset. You will search a subreddit or topic, collect matching posts, open each thread, capture comment context, and make later runs comparable without rereading the same discus
Decide whether you need discovery, thread tracking, or both
“Monitor Reddit posts and comments” can describe three different jobs:
Monitoring job | Starting point | What should change on later runs? |
Discover relevant discussions | Subreddit plus search query | New matching posts appear |
Capture discussion context | A batch of discovered post URLs | Visible comments and replies are collected |
Follow one important thread | One known post URL | Only new comments or changed activity return |
Keeping those jobs separate prevents a common mistake. A search feed can tell you that a post has 43 comments, but it does not contain the full discussion. A post page exposes the thread, yet following every comment under every discovered post can make the run slow and expensive. Decide which posts deserve comment collection before opening everything.
Choose a narrow discovery query
Begin with one subreddit and one phrase. A focused test is easier to evaluate than an all-Reddit sweep.
For example:
- Subreddit:
SaaS - Search query:
social listening software - Sort:
new - Post count:
20 - Include comments:
true
Reddit supports field filters such as subreddit:, title:, selftext:, author:, site:, and url:. Its current search documentation also supports the uppercase Boolean operators AND, OR, and NOT, plus parentheses for grouping. These can make a discovery query more precise:
("social listening" OR "brand monitoring") NOT hiring
Use quotation marks for multi-word field searches. Reddit notes that post searches may match only some of the words unless special syntax forces a tighter match, while comment searches currently require all search words. Test the query manually before automating it so you know what the result page actually returns.
Design the output around two connected records
Posts and comments should not become one ambiguous text column. Treat them as related records.
Post record
Keep:
- post URL;
- title and visible post text;
- subreddit and author;
- publication date;
- score and comment count;
- discovery query and source page URL;
- collection time.
Comment record
Keep:
- parent post URL;
- comment author and visible text;
- comment score and visible creation time;
- comment permalink or ID when the page exposes it;
- parent comment reference when collecting nested replies;
- collection time.
The post URL connects every comment back to the discussion that gives it meaning. A short reply such as “we switched last month” is nearly useless without the parent post and the comment it answers.
Build the posts-and-comments monitor in BrowserAct
BrowserAct’s Reddit Posts and Comments Scraper accepts a subreddit, search query, sort mode, comment option, and result count. The current template returns post fields and can open each post detail page to collect visible top comments when include_comments is enabled.
The template page estimates 17–45 credits per run. Actual use depends on how many posts you request and whether the Bot opens each detail page for comments, so test with five posts before moving to 20 or more.
1. Open BrowserAct Dashboard
Click the left-side + Create button to build a Bot, choose Scrape Reddit Posts or Scrape Reddit Comments from the Social Media quick-start menu, or paste the prompt into the center Agent input.
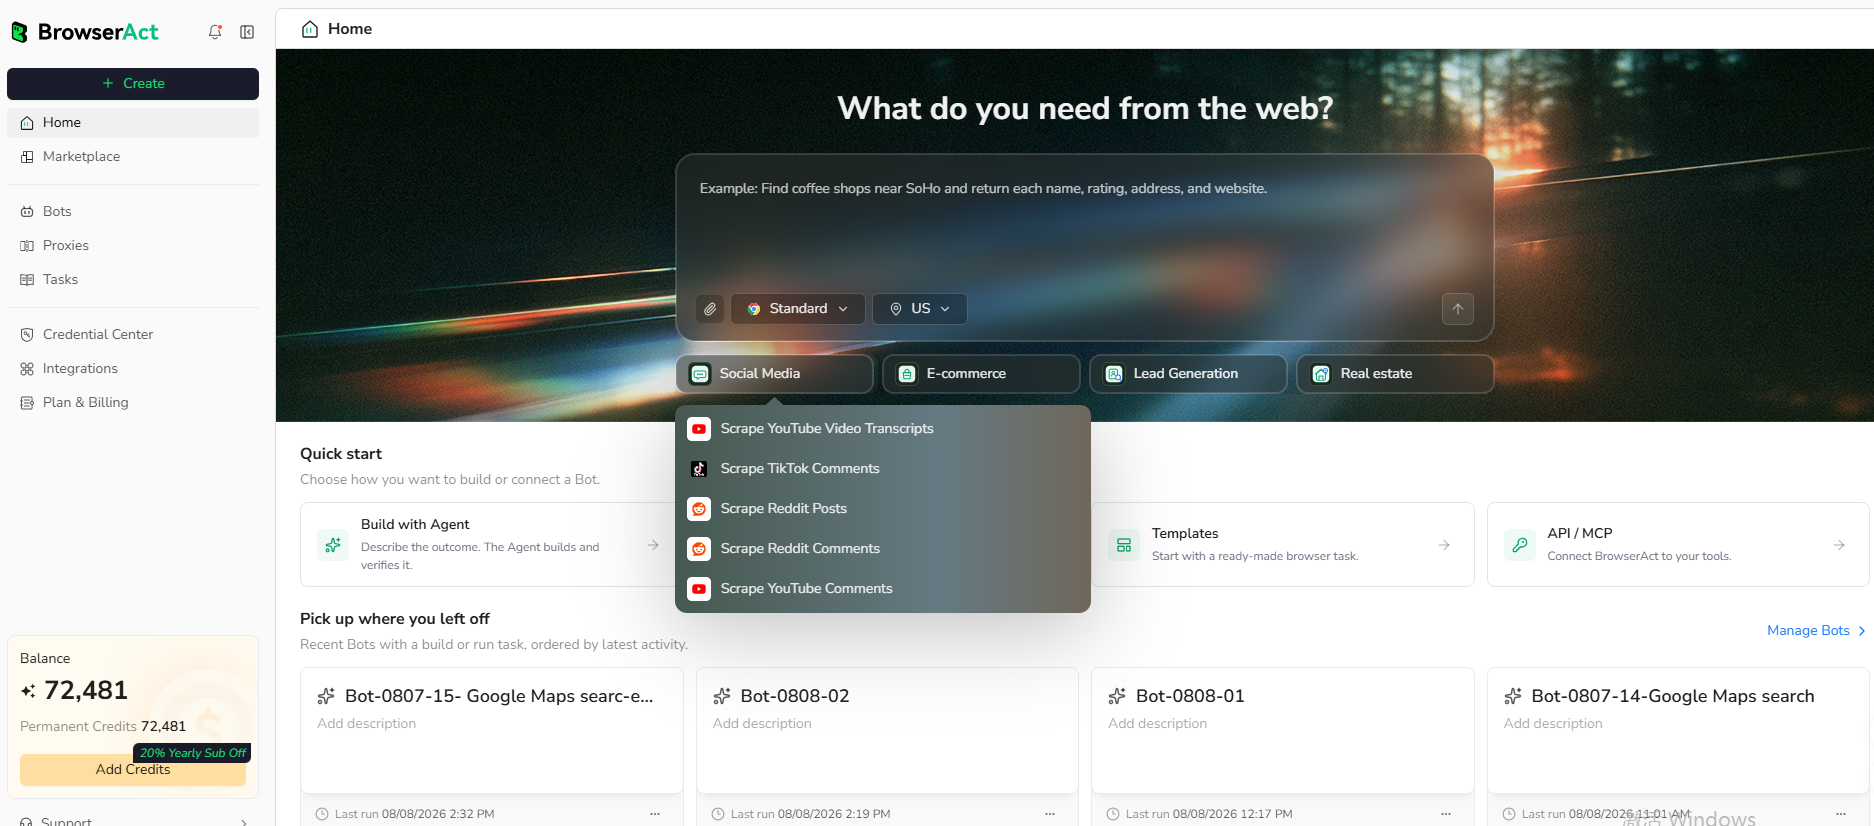
2. Copy the complete prompt
Change the subreddit, query, and post limit for your use case. Leave the record structure intact during the first run.
Create a reusable Bot that monitors public Reddit posts and their visible comments.

Inputs:
- subreddit: SaaS
- search_query: "social listening software" OR "Reddit monitoring tool"
- sort: new
- include_comments: true
- count: 20

Workflow:
1. Open the public subreddit search page for the supplied subreddit and search query.
2. Sort the post results by New.
3. Scroll until you collect up to the requested number of unique public posts.
4. Open each collected post and capture up to 10 visible top comments.
5. Return the post and comment context in structured form.

For each post return:
- title
- url
- subreddit
- author
- score
- comment_count
- created_date
- post_text
- external_link
- rank
- source_page_url
- collected_at

For each visible comment return:
- parent_post_url
- comment_author
- comment_text
- comment_score
- comment_created_date
- comment_permalink or comment_id when visible
- parent_comment_reference when visible
- collected_at

Deduplicate posts by url. Deduplicate comments by comment_permalink or comment_id when available. If neither is visible, use a composite key made from parent_post_url, comment_author, comment_text, and comment_created_date.

On later runs, label post rows and comment rows as new, updated, or previously_seen when a previous export is provided. Preserve updated comment_count and score values instead of deleting an existing post record.

Use public or authorized pages only. Do not join a subreddit, vote, comment, follow, message users, or change an account. If Reddit requests login, CAPTCHA, 2FA, age confirmation, membership approval, or another restricted-access action, pause and ask me to complete it manually.

Return a CSV-ready table and JSON. Keep the original Reddit URLs in the output.
Why the prompt limits comments: opening every thread and expanding every reply can dominate the run. Ten visible top comments per post gives you a useful first-pass sample. Increase the limit only for discussions that matter.
Scrape data from any website. Describe the data you need. Get a Bot—a reliable, reusable scraper. Try: “Find 20 new posts in r/SaaS and capture the visible top comments with each post URL.” Get your Bot — Free
3. Handle login only when asked
The template is designed for public Reddit pages and does not require a Reddit login for its normal public workflow. If Reddit presents a login, CAPTCHA, 2FA, age gate, or another access check, allow BrowserAct to pause. Complete the requested step yourself and resume only when you are authorized to view the page.
Do not convert a read-only monitor into an automatic engagement Bot. Replies, votes, messages, and community actions should remain separate and human-reviewed.
4. Review, dedupe, and export
Run the Bot with five posts first. Confirm that the title, post URL, comment count, source page, and visible top comments match the actual Reddit pages. Optional values such as an external link or visible author may be empty when Reddit does not display them.
Check the comment output separately. Every comment needs its parent post URL. If a permalink or comment ID is unavailable, retain the composite key fields exactly as collected so later runs can compare them consistently.
Export the cleaned result as CSV or JSON. A relational setup can store posts and comments in separate tables; a lightweight spreadsheet can keep one post row with a nested top_comments JSON column.
A publication-ready version will place a real Reddit run result screenshot here. The generic result screenshot supplied on the template page was not used because it showed an unrelated Amazon dataset.
How to compare later runs
The post and comment layers change at different speeds. Compare them separately.
For posts:
- New: the post URL has not appeared before.
- Updated: the post URL exists, but score, comment count, or visible text changed.
- Previously seen: the post exists and no tracked field changed.
For comments:
- New: the permalink, ID, or composite key has not appeared before.
- Updated: a known comment has a changed score or visible text.
- Previously seen: the identity and tracked values match the earlier export.
Keep first_seen_at and last_seen_at in the master dataset. Do not overwrite Reddit’s creation time with the collection time. The difference tells you whether a comment was posted recently or merely discovered late.
Prevent one busy post from consuming the run
A popular post can contain hundreds or thousands of comments. If the purpose is market research, collect a controlled sample across more posts instead of exhausting one thread.
A practical first run is:
Setting | Starting value | Why |
Posts | 10–20 | Enough breadth to judge query quality |
Visible top comments | 5–10 per post | Adds context without overwhelming the run |
Sort | New | Finds current discussions |
Frequency | Daily | Establishes baseline volume |
Deep follow-up | Only selected post URLs | Saves cost for important discussions |
- comment count grows quickly;
- the thread mentions your product or a competitor;
- a complaint needs support review;
- several commenters repeat the same problem;
- the post is tied to a launch, AMA, incident, or campaign.
The discovery Bot finds candidates. A post-comments Bot follows the candidates that justify deeper monitoring.
Keep the conversation structure during analysis
Flattening every comment into a bag of text can reverse its meaning. A reply saying “that fixed it” should remain connected to the recommendation it confirms. Preserve at least the parent post URL and, when visible, the parent comment reference or depth.
For sentiment or product-feedback analysis, group comments by post before summarizing them. Start with the post question, then read the top-level comment and its replies as one mini-conversation. This produces better issue labels than classifying each sentence in isolation.
Reddit’s own interface provides comment search within a specific post, and its post/comment insights distinguish metrics such as comments, replies, scores, and views for content a user created. Those features reinforce the same principle: a post and its comment tree are related but different objects.
Common failures and the fix
The Bot collects posts but no comments
Confirm that include_comments is true and that the workflow opens each post URL. A search-results page usually exposes a comment count, not the full comment text.
The same posts return every day
Store the post URL from the first run and compare against it. Repeated collection without a stable key is a search export, not a monitoring system.
Short replies look irrelevant
Include the parent post URL and parent comment context. Do not classify a reply without the sentence or question it answers.
Runs become slow or expensive
Reduce the post count or comment limit. Use the discovery run to decide which threads need deeper tracking instead of expanding every discussion.
Comment duplicates remain
Prefer a comment permalink or ID. When the page does not expose one, construct the same composite key every time and accept that edited or deleted comments may require manual review.
Final checklist
- Define one subreddit, one query, one sort, and a small post limit.
- Keep posts and comments as connected but separate records.
- Preserve the parent post URL for every comment.
- Start with five posts and a small visible-comment sample.
- Deduplicate posts by URL and comments by permalink, ID, or a stable composite key.
- Store publication time separately from collection time.
- Compare posts and comments independently on later runs.
- Move only important threads into deeper comment monitoring.
- Keep collection read-only and engagement human-reviewed.
Once this workflow is reliable for one subreddit, reuse it with new query inputs. Changing the input is easier to audit than rebuilding the Bot for every topic.
Frequently Asked Questions
Can Reddit search both posts and comments?
Yes; Reddit supports comment search and post search, but a monitoring workflow still needs to preserve the post that gives each comment its context.
Does the BrowserAct template collect every Reddit comment?
No; the current template can collect visible top comments, and the practical limit depends on the page, settings, and how much of the thread is expanded.
How should I deduplicate Reddit comments?
Use a comment permalink or ID when available; otherwise combine the parent post URL, author, text, and visible creation time into a consistent key.
Should posts and comments go into the same spreadsheet?
They can, but separate post and comment tables are easier to update; always keep the parent post URL on every comment row.
When should I monitor one Reddit post instead of a search query?
Use a single-post monitor for launches, AMAs, complaints, incidents, or any thread where new replies matter more than discovering additional posts.


