How to Monitor Reddit for Keywords: A Repeatable Workflow

If you search Reddit only when someone remembers, you are researching—not monitoring. A useful Reddit keyword monitoring workflow runs the same searches on a schedule, sorts the newest discussions first, saves enough context to judge each match, and separates genuinely new posts from URLs you have already reviewed. This guide shows how to build that workflow for public Reddit posts with BrowserAct. The goal is a clean table of new discussions, not an inbox full of every post containing a common
The workflow at a glance
You will:
- Build a small keyword set that represents the conversations you actually want.
- Search Reddit and use New sorting to prioritize recent posts.
- Save the title, subreddit, URL, publication time, and engagement context for each match.
- Run the same collection again and use the post URL as the deduplication key.
The last step is what turns a Reddit search into monitoring. Without a stable ID or URL, every run produces another pile of results and forces you to reread old posts.
Start with keyword groups, not one generic term
A product name is only one way a useful conversation can appear. Someone ready to switch tools may never mention your category or brand. Build a compact list across four groups:
Keyword group | What it catches | Example for a social listening product |
Brand variants | Direct mentions and misspellings |
|
Competitor phrases | Comparisons and switching signals |
|
Category phrases | People naming the solution |
|
Problem phrases | People describing the need |
|
monitoring, listening, or alerts usually create too much noise. A phrase like Reddit keyword alerts carries more intent and is easier to review.
Add spelling variants as separate searches instead of assuming one query will catch them. For competitive research, combine a competitor name with terms such as alternative, pricing, problem, switched, or recommend.
Validate the searches manually before automating
Open Reddit search, enter one phrase, and inspect the first page of results. Change the sort from Relevance to New. Reddit’s official search documentation says that New prioritizes the most recent posts regardless of votes or comments, while Relevance also weighs word rarity, age, votes, and comments. That makes New the safer default for monitoring.
Use this short validation pass to answer three questions:
- Does the phrase return conversations about the intended topic?
- Do the useful results come from all of Reddit or a small set of subreddits?
- Are the title and snippet enough, or must you open each post to judge relevance?
If most matches are irrelevant, narrow the phrase or restrict the collection to known communities. If the same unrelated meaning appears repeatedly, record it as an exclusion rule for the review stage.
Reddit also supports time filters and other sorts. Hot is useful for fast-moving discussions, Top for well-known posts, and Comment Count for threads with active conversation. Keep New for the monitoring run; use the other sorts in a separate discovery run so old popular threads do not crowd out recent posts.
Build the Reddit keyword monitor in BrowserAct
BrowserAct’s Reddit Keyword Intelligence Scanner is designed for this job. It searches Reddit using an input keyword, applies a sort, opens matching posts, and returns structured fields such as titles, URLs, publication times, and post content.
Use the following four-action setup for a new Bot or adapt the ready-made template.
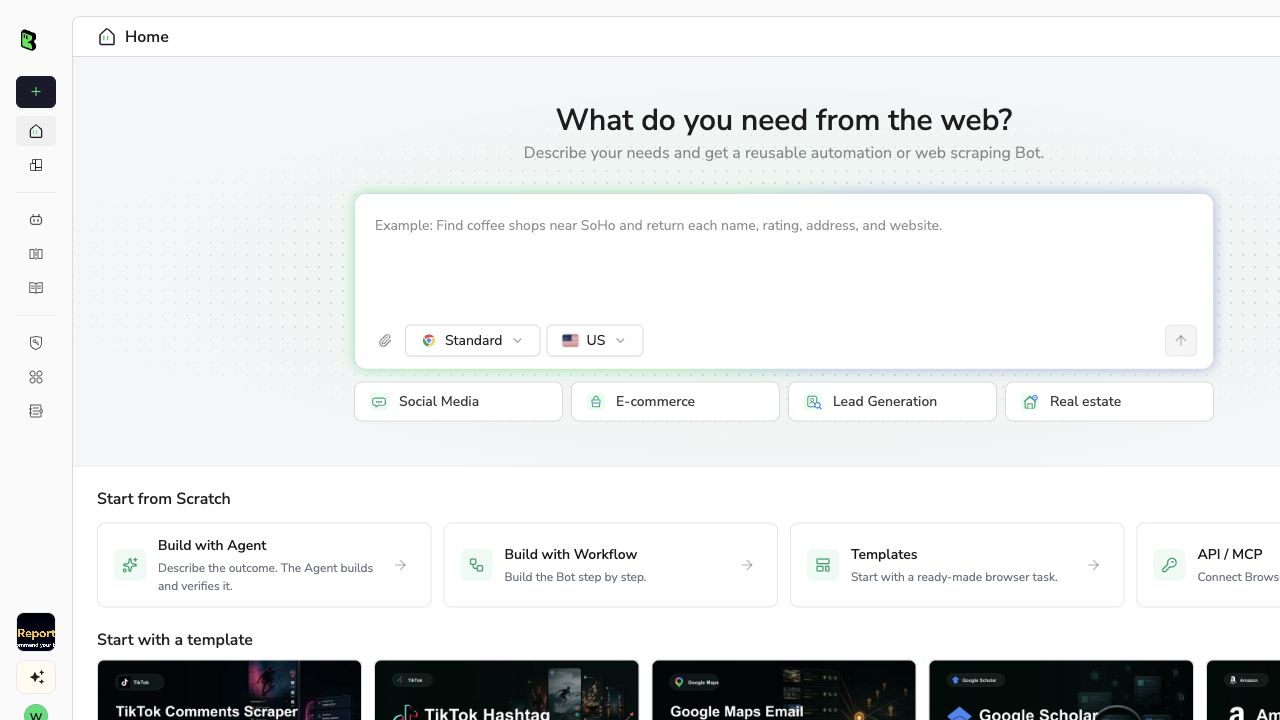
1. Open BrowserAct Dashboard
Click the left-side + button to create your own Bot, start from Quick start, or paste the prompt directly into the center Agent input to begin building.
2. Copy the complete prompt
Replace the example keywords with your own. Keep the output fields and deduplication rules intact until the first test run works.
Create a reusable Bot that monitors public Reddit posts for these keywords:

- "social listening software"
- "Reddit monitoring tool"
- "Brand24 alternative"
- "how do I track Reddit mentions"

For each keyword:
1. Open Reddit search and search the exact phrase.
2. Select Posts and sort the results by New.
3. Collect up to 25 visible public posts from the newest results.
4. Open a result only when needed to capture the requested visible fields.

Return one structured row per post with:
- keyword_used
- subreddit
- post_title
- post_url
- author
- published_at
- score
- comment_count
- visible_snippet
- collected_at

Deduplicate all rows by post_url. If a previous results file or table is supplied on a later run, compare against its post_url column and label each row as new or previously_seen. Return new rows first.

Use only information visible on public pages. Do not join communities, vote, comment, message users, or change an account. If Reddit requests login, CAPTCHA, 2FA, membership confirmation, or another restricted-access action, pause and ask me to complete it manually.

Output both a CSV-ready table and JSON. Preserve the original Reddit URL for every row.
Why the prompt includes keyword_used: when several searches feed one table, this column shows which rule found the post. It becomes the fastest way to prune noisy keywords later.
Scrape data from any website. Describe the data you need. Get a Bot—a reliable, reusable scraper. Try: “Find the newest public Reddit posts matching these four phrases and return a deduplicated table.” Get your Bot — Free
3. Handle login only when asked
Most public search results can be reviewed without an account, but Reddit may occasionally request a login or verification. Let BrowserAct pause, complete the requested login, CAPTCHA, 2FA, membership approval, or account confirmation yourself, and then resume the run.
Do not design the Bot to join communities, vote, comment, or send messages. Monitoring and engagement are separate workflows, and any response should stay under human review.
4. Review, dedupe, and export
Inspect the structured rows before scheduling the Bot. Remove irrelevant matches and malformed rows, then confirm that every result has a valid post_url and published_at value. Export the cleaned output as CSV or JSON; a Markdown or Sheets-ready table also works for a lightweight review process.
Use post_url as the primary deduplication key. Store collected_at separately from Reddit’s publication time so you can distinguish when a post was created from when your monitor first found it.
The publication version will include a real BrowserAct export screenshot here after the first monitored run. No sample result is fabricated in this review draft.
How to identify only new Reddit posts on the next run
Keep the result file from run one. On run two, compare every collected post_url with the stored URL column:
- A URL that does not exist in the earlier file is new.
- A known URL with a changed comment count or score is updated.
- A known URL with no material change is previously seen and can leave the review queue.
This three-state model is more useful than deleting all duplicates. A post you found yesterday may gain 100 comments today, making it relevant again even though the URL is unchanged.
For a simple spreadsheet workflow, maintain one master tab and append only new URLs. Keep first_seen_at, last_seen_at, and latest_comment_count. For a database, make post_url unique and update the existing row when engagement changes.
Choose a schedule based on the action you will take
More frequent collection is useful only when someone can act on the result.
Monitoring job | Practical starting cadence | Review action |
Product complaint or launch monitoring | Every 2–4 hours | Route urgent matches to support or communications |
Recommendation and lead-intent phrases | Every 4–6 hours | Review quickly while the discussion is active |
Competitor and category research | Daily | Tag themes and save useful language |
Content and market research | Weekly | Summarize recurring questions and topic changes |
Reduce noise after the first week
Keyword monitoring usually fails because teams keep adding phrases without removing weak ones. Review the first week by keyword_used and calculate three simple counts:
- total matches;
- relevant matches;
- matches that led to an action, insight, or saved example.
Pause phrases that produce volume without value. Split ambiguous searches by subreddit or add another qualifying word. If a problem phrase finds the best conversations, promote it to a higher-frequency run even if its total volume is low.
Some tools apply semantic or AI classification after collection. That can help, but start with transparent keyword rules and retain the original post URL. You should be able to explain why each result entered the queue before adding an opaque relevance score.
When to use Reddit Pro or a simple alert tool instead
BrowserAct is useful when you need repeatable navigation, custom visible fields, structured exports, and a dataset you can compare across runs. It is not the smallest solution for every job.
Use Reddit Pro Trends if your eligible business wants an official dashboard for tracking keywords, discovering communities, and reviewing conversations. Reddit says the feature uses public, safe-for-work English communities and excludes private, banned, quarantined, NSFW, deleted, and some sensitive content. Reddit also restricts downloading other users’ posts and comments from Reddit Pro, so review its usage terms before treating it as an export source.
Use a simple service such as F5Bot when email alerts for a few narrow keywords are enough. Its current product page says it monitors Reddit, Hacker News, and Lobsters and emails matches from new posts or comments. It is a good baseline when you do not need custom extraction, a controlled table, or your own deduplication logic.
Use manual Reddit search for occasional research. It costs nothing and helps you refine the phrase list, but it is easy to miss a day and difficult to prove which results were new.
What this workflow does not cover
This article monitors new public posts. Comment-level monitoring needs a different workflow because comments may appear long after a post is published and require their own stable IDs. If your target is a known launch, AMA, support complaint, or product-feedback thread, use a post-comments monitor and deduplicate by comment URL or comment ID.
The workflow also does not promise access to private, deleted, quarantined, restricted, or otherwise unavailable content. Collection should stay within public or authorized pages and the applicable platform rules.
Final checklist
- Use specific multi-word phrases and known variants.
- Validate each search manually before automating it.
- Sort monitoring searches by New.
- Save
keyword_used,post_url,published_at, andcollected_at. - Deduplicate by URL while still tracking engagement changes.
- Set the schedule according to the action your team can take.
- Review keyword quality after one week and remove noisy searches.
- Keep engagement manual and separate from data collection.
Once that loop works for one keyword, add the rest gradually. A small monitor that reliably surfaces five useful posts is more valuable than a large one that delivers hundreds of matches nobody reads.
Frequently Asked Questions
Can Reddit notify me when a keyword is mentioned?
Reddit Pro Trends can track keywords for eligible businesses, while third-party tools and automated BrowserAct workflows can provide different alerting or export options.
Should I sort Reddit keyword searches by New or Relevance?
Use New for recurring monitoring because it prioritizes recent posts; use Relevance separately when researching the strongest historical matches.
How do I avoid collecting the same Reddit post twice?
Store each post URL and compare that field on every later run, while retaining engagement changes as updates.
Can this workflow monitor Reddit comments too?
The prompt above targets posts; comment monitoring should use a separate workflow and deduplicate each result with a comment URL or comment ID.
How many Reddit keywords should I monitor first?
Start with five to ten specific phrases, review their relevance for one week, and expand only after removing noisy searches.


