
YouTube Comments Scraper
YouTube Comments Scraper is a reusable BrowserAct template for collecting structured records from public YouTube pages.
Published by
Br
BrowserAct Team
September 14, 2026
Approx.Credits
18-54 Credits
Categories
BA
APIYoutube
Template ID
113862683031243687

Brief
YouTube Comments Scraper is a reusable BrowserAct template for collecting structured records from public YouTube pages. Configure the run inputs, start the Bot, and receive consistent output for research, monitoring, enrichment, or downstream automation without writing selectors or scraper code.
What Does BrowserAct YouTube Comments Scraper Do?
The Bot starts from your configured inputs, opens the relevant public YouTube page, loads the requested records, extracts the visible fields, and returns structured results. The default example uses https://www.youtube.com/watch?v=_ba9kScc85M for Video URL, but the input can be changed before each run.
Key Features of YouTube Comments Scraper
- Configurable public-page inputs without rebuilding the Bot.
- Structured records returned in a consistent
resultsarray. - Public, non-login extraction path.
- Reusable runs for new keywords, URLs, locations, or limits.
- Output ready for review, export, API use, or automation.
What Data Can I Extract from YouTube?
Field | Description |
|---|---|
| Publicly visible comment author value for the record, when available. |
| Publicly visible author channel url value for the record, when available. |
| Publicly visible comment text value for the record, when available. |
| Publicly visible published time value for the record, when available. |
| Publicly visible like count value for the record, when available. |
| Publicly visible reply count value for the record, when available. |
| Publicly visible comment url value for the record, when available. |
| Publicly visible is pinned value for the record, when available. |
| Publicly visible creator hearted value for the record, when available. |
| Publicly visible video title value for the record, when available. |
| Direct public video URL. |
| Record position in the collected result order. |
How to Use YouTube Comments Scraper
Quick Start Guide
- Click Run task.
- Keep the default inputs for a first test or enter your own public-page values.
- Click
Run. - Review the structured records after the run completes.
- Download the result or connect it to another workflow.
Input Parameters
Parameter | Required | Default | Description |
|---|---|---|---|
| Yes |
| Controls the video url used for this run. |
| Yes |
| Controls the max comment count used for this run. |
Example Output
The table below uses records preserved from the validated Bot run. Up to the first 5 records are shown, and long values are shortened in this documentation preview.
comment_author | author_channel_url | comment_text | published_time | like_count | reply_count | comment_url | is_pinned | creator_hearted | video_title | video_url | rank |
|---|---|---|---|---|---|---|---|---|---|---|---|
Example value | Example value | Example value | null | null | false | Example value | Example value | 1 |
How Does it Work?
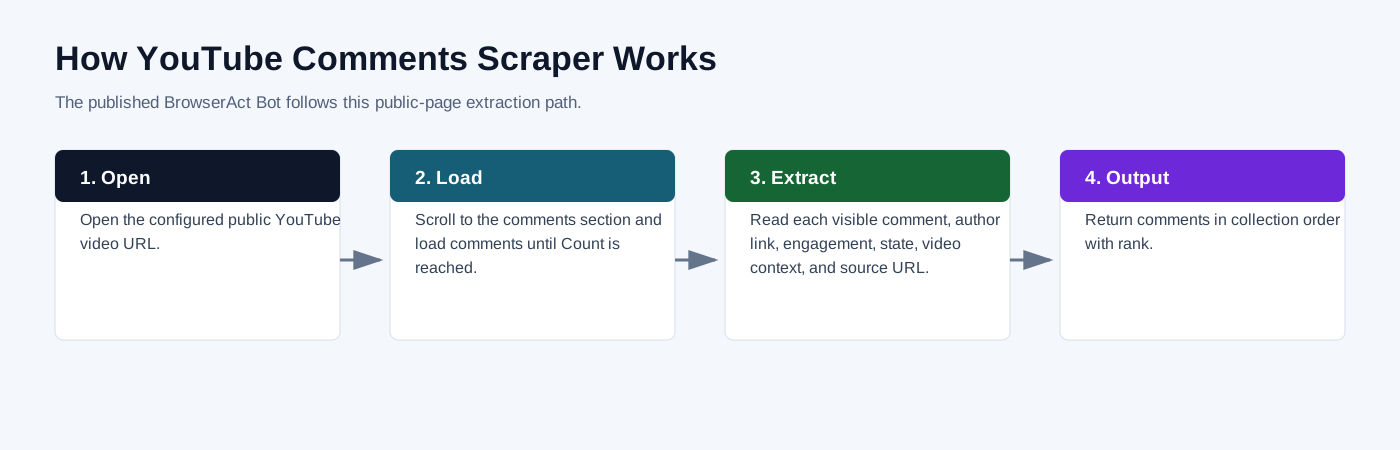
- Open the configured public YouTube video URL.
- Scroll to the comments section and load comments until Count is reached.
- Read each visible comment, author link, engagement, state, video context, and source URL.
- Return comments in collection order with rank.
How to Build a New Scraper Bot with Agent Built
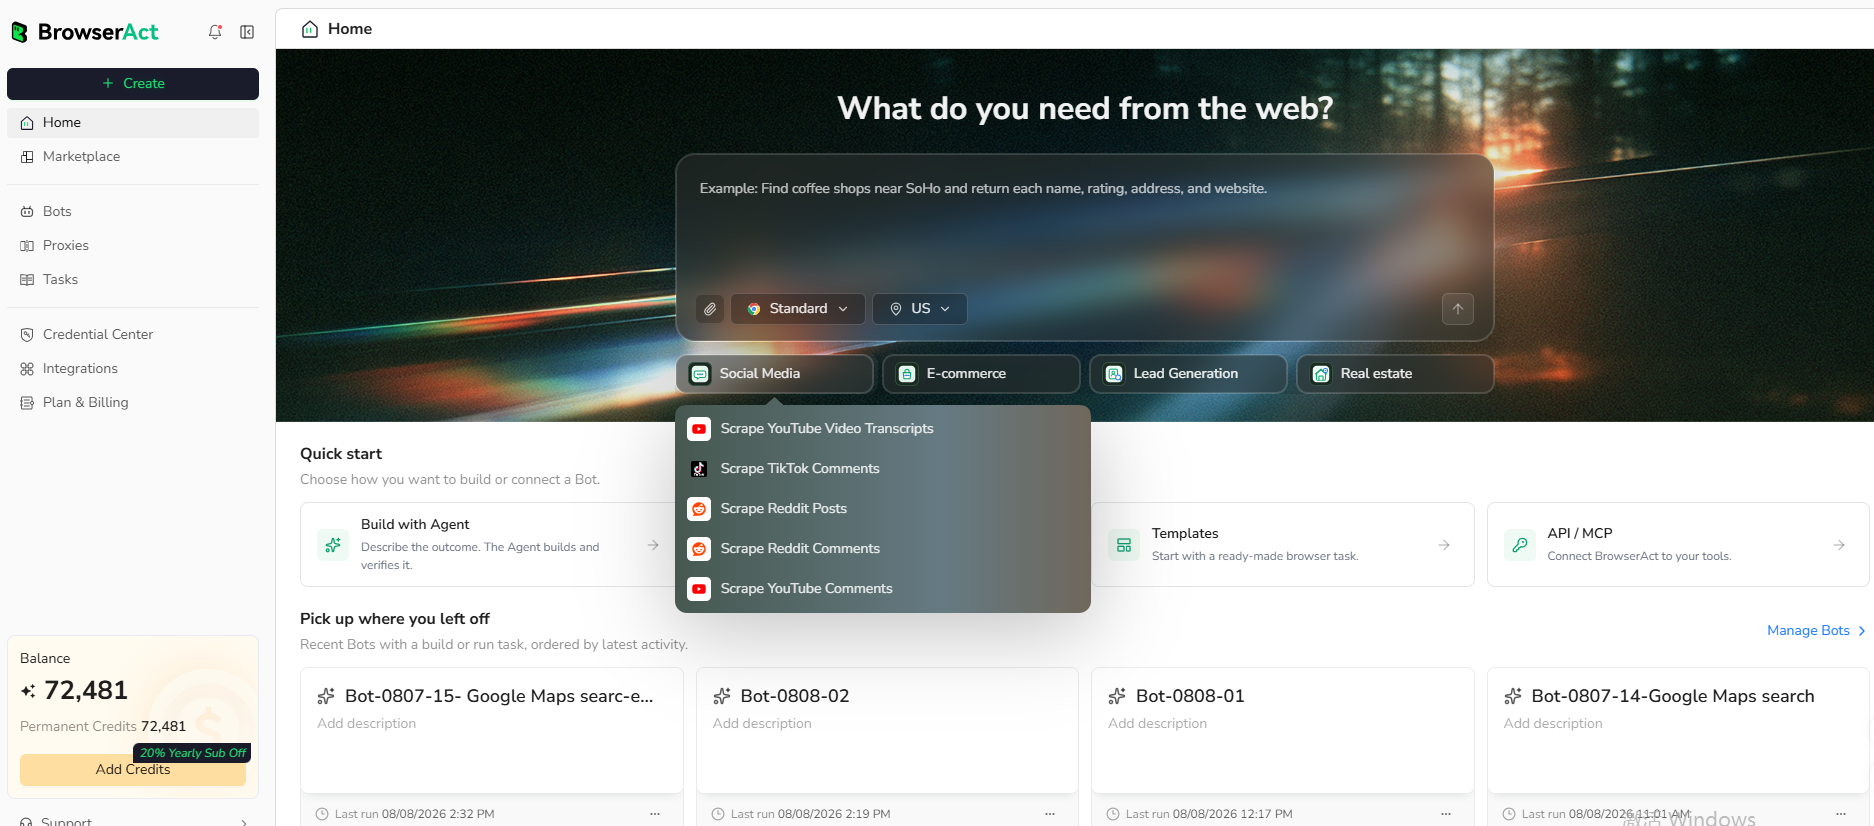
Step 1: Describe the data you need
Open BrowserAct and start Agent Built from the Home prompt box or from Create -> Build with Agent. Describe the public website, records, inputs, fields, and result limit.
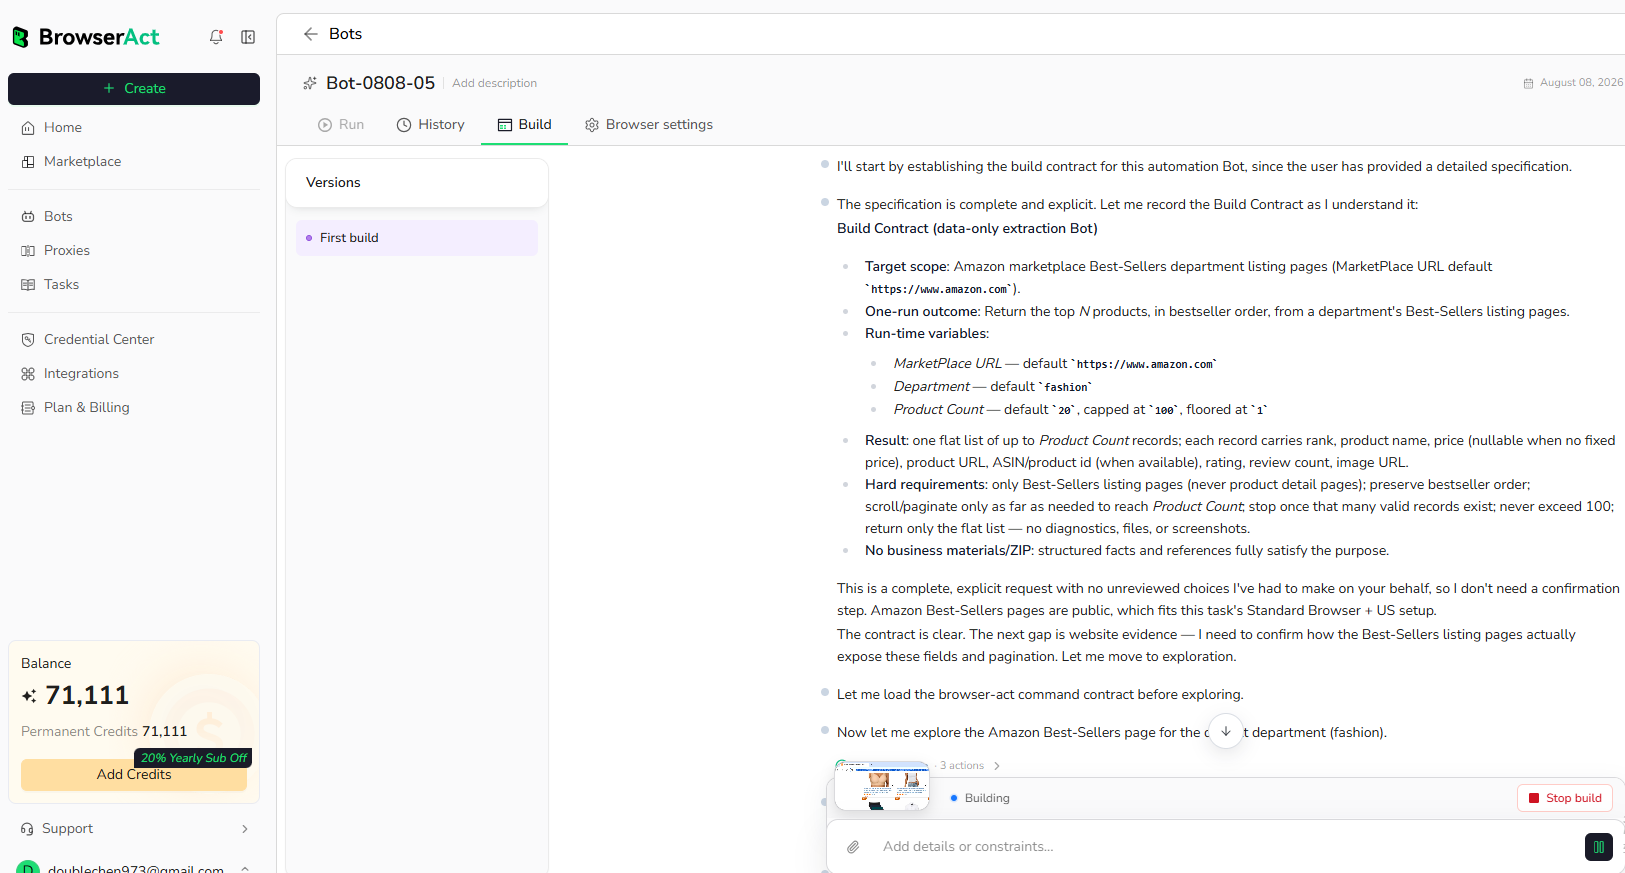
Step 2: Let BrowserAct build and test the Bot
BrowserAct explores the live website, determines the navigation and extraction path, and validates the result. Reply in the same build conversation if the Agent requests a missing public URL, field, or expected output.
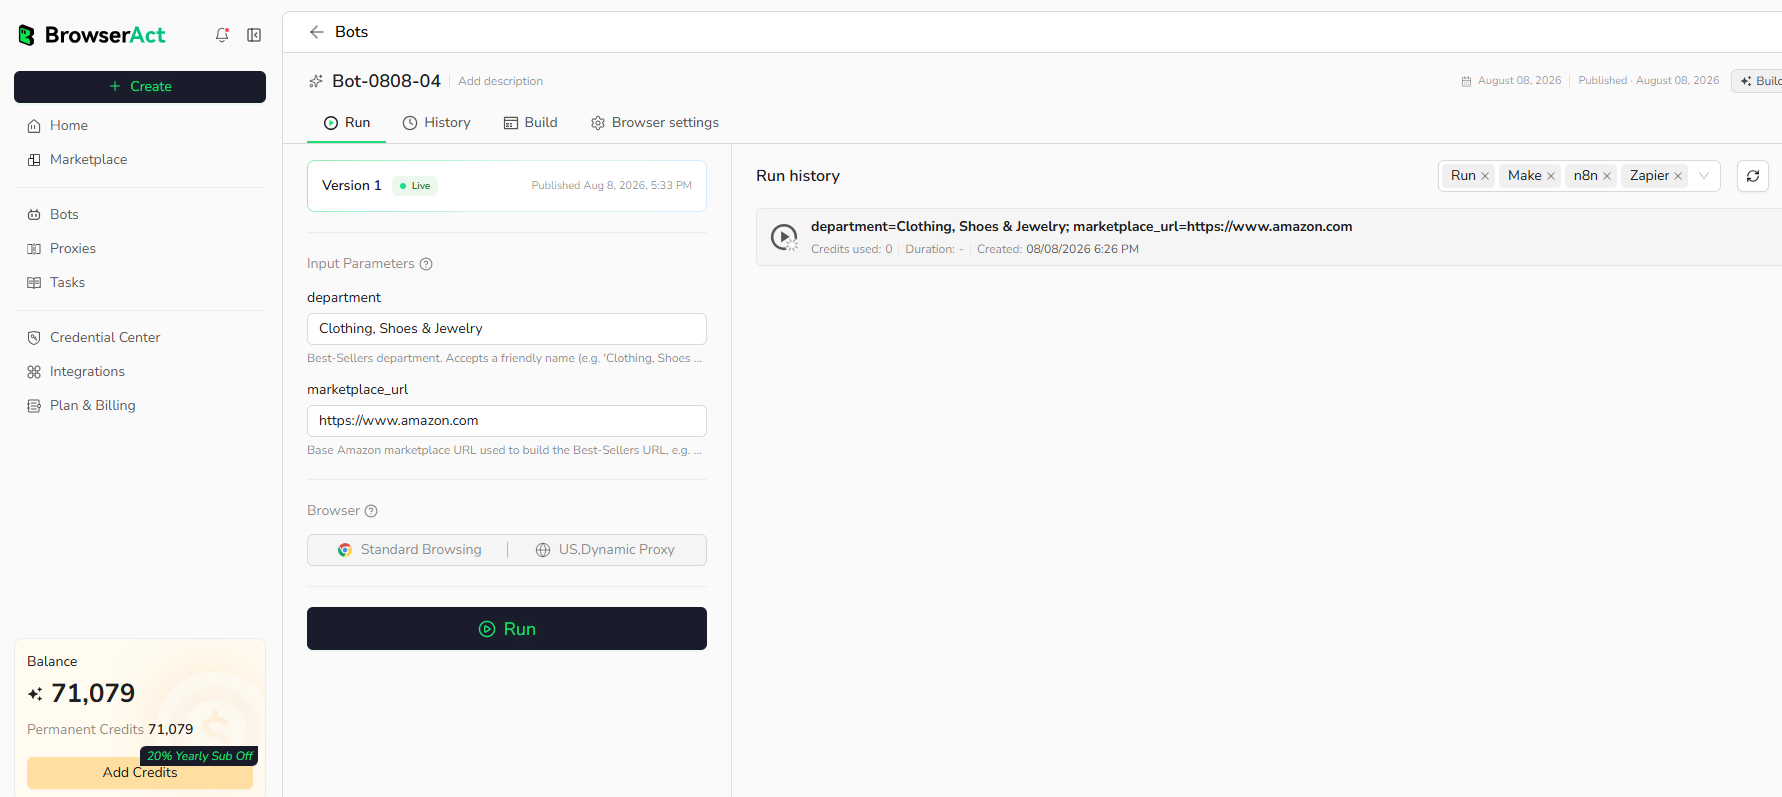
Step 3: Run the Bot and review the result
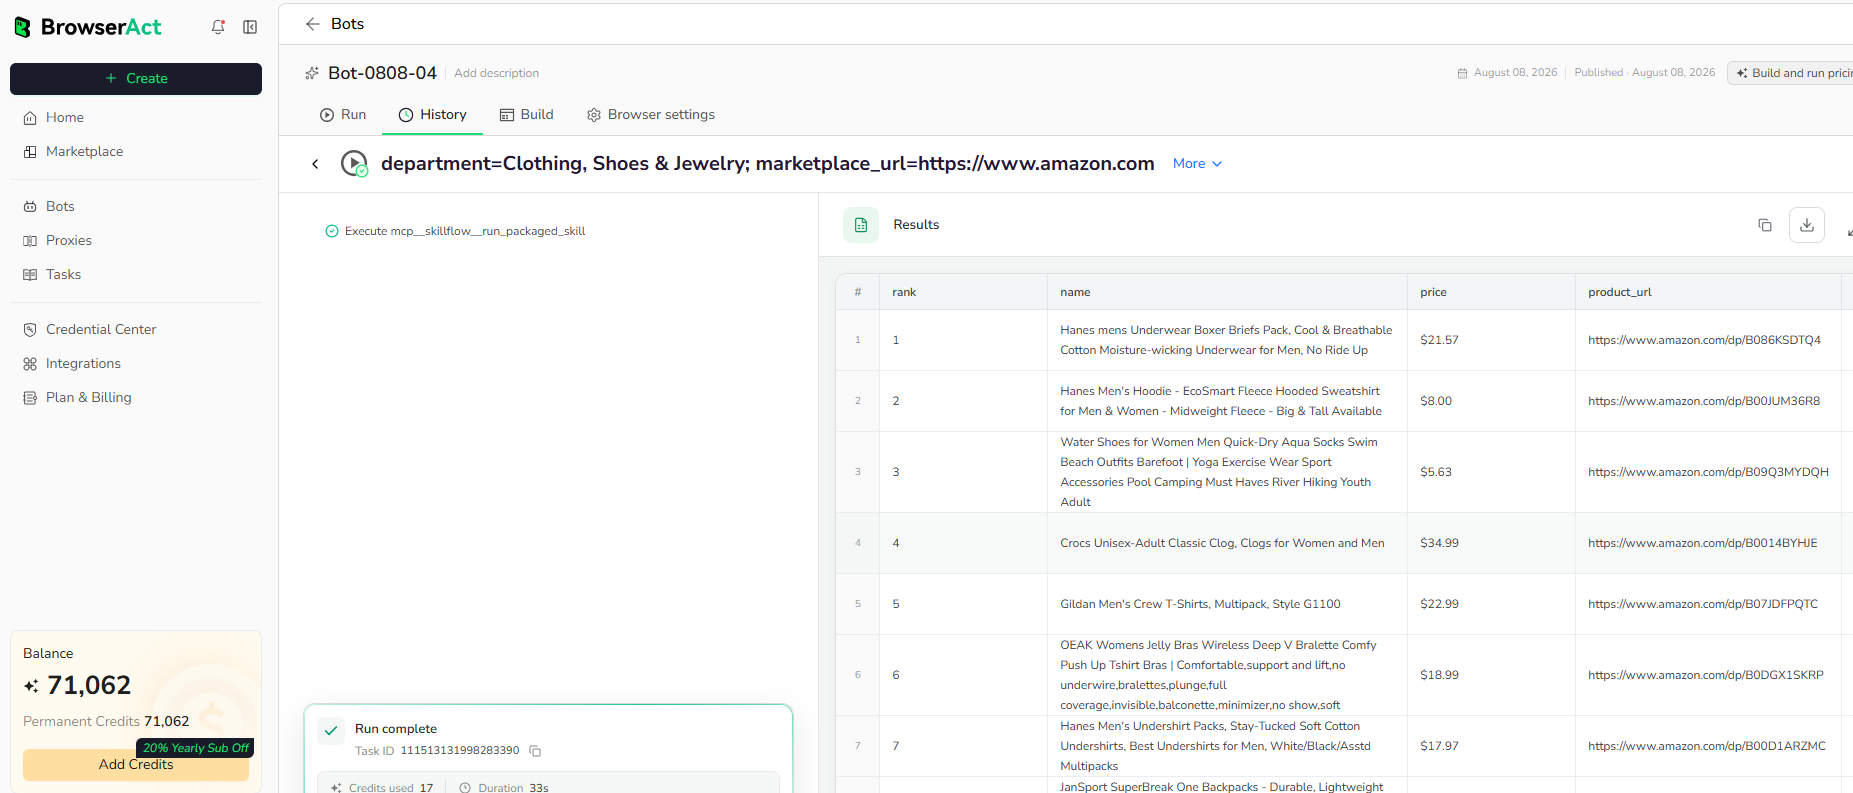
Run the completed Bot with default inputs. Check record count, source URLs, and required fields before reusing it with new inputs.
Why Use YouTube Comments Scraper?
- Replace repetitive copying from public YouTube pages.
- Keep the same output structure across repeated runs.
- Send public records into research, reporting, enrichment, or monitoring workflows.
Who Can Use YouTube Comments Scraper?
- Researchers and analysts collecting public web data.
- Marketing, sales, and operations teams preparing structured datasets.
- Automation builders connecting BrowserAct output to other tools.
- Developers who need reusable browser-collected JSON records.
Automation and Export
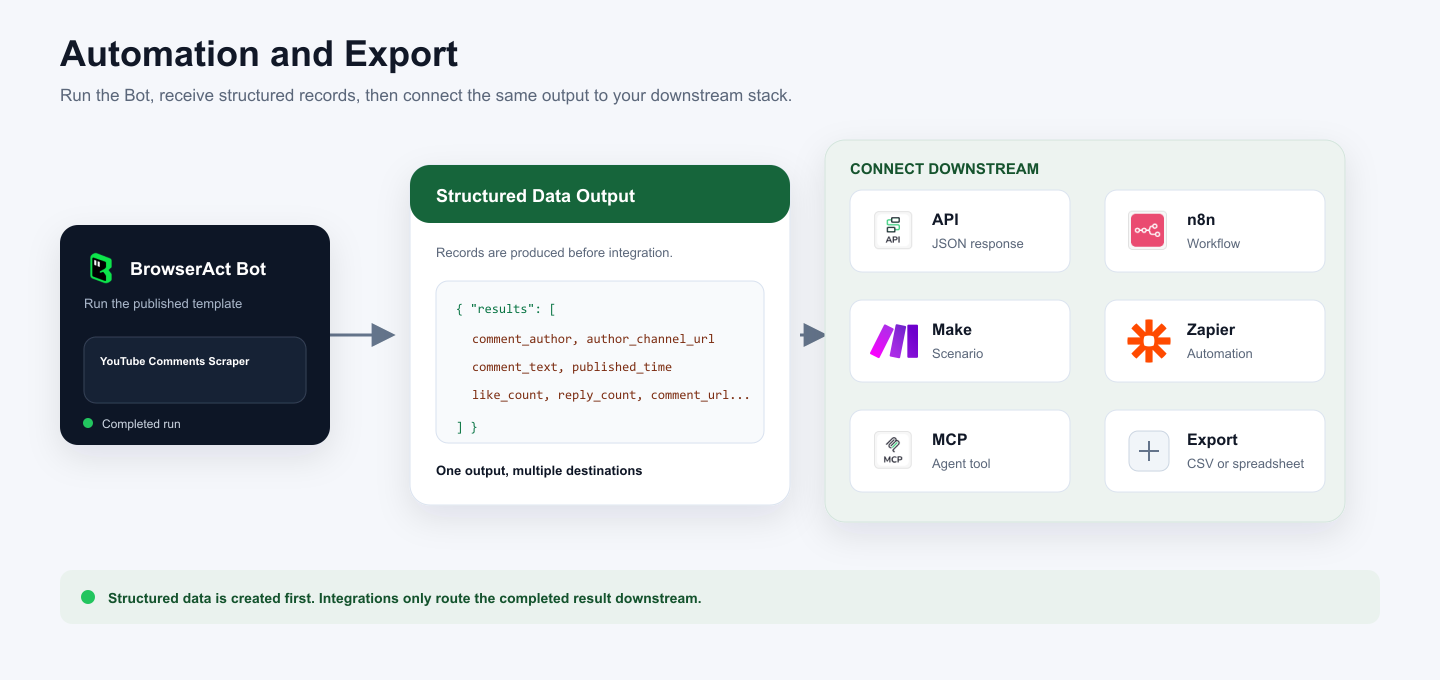
BrowserAct returns structured records first. You can then use that output through API JSON responses, n8n workflows, Make scenarios, Zapier automations, MCP-based agent workflows configured from the Bot's Integrations tab, or manual spreadsheet export.
Need Help?
Contact us at
Discord: Discord Community
E-mail: service@browseract.com
 What can we do for you