

What Does BrowserAct Xiaohongshu Notes Scraper Do?
Collect keyword-matching Xiaohongshu notes, including titles, body text, creators, publish times and engagement counts, with BrowserAct. Use the individual records to research content themes, compare creators and organize social-content research without writing a scraper.
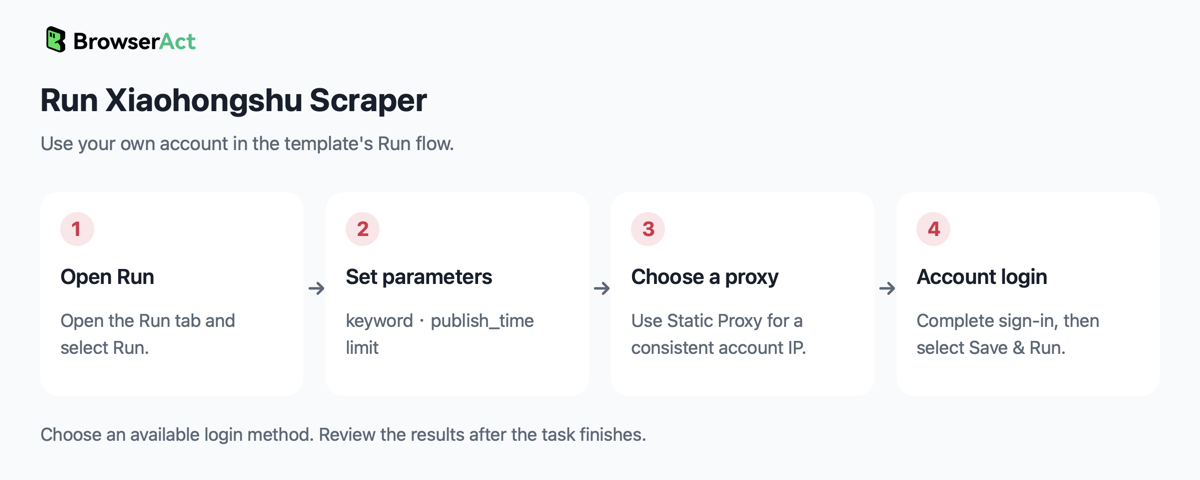
Your Xiaohongshu login is required. Click Run, enter the search settings, then continue to Account login to choose a proxy and connect your own account before starting.
Key Features of Xiaohongshu Notes Scraper
- Find image/text and video notes for a keyword and publish-time window.
- Collect note body text and topic tags for content and brand research.
- Keep notes that match all the supplied keyword terms.
- Compare creators and visible like, favorite and comment counts.
What Data Can I Extract from Xiaohongshu?
| Field | What you receive |
|---|---|
keyword |
Search keyword |
note_id |
Note ID |
note_url |
Note link |
title |
Note title, when present |
body |
Note body text |
note_type |
Image/text note or video note |
author_nickname |
Creator nickname |
author_profile_url |
Creator profile link |
published_at |
Publish time in Beijing time |
tags |
Topic tags |
likes |
Like count |
collects |
Favorite count |
comments |
Comment count |
How to Use Xiaohongshu Notes Scraper
- Open Run task and click Run.
- Enter the keyword, choose the publish-time window and set the requested quantity. Continue to Account login.
- Choose a proxy. A Static Proxy is recommended when you need a consistent IP for the account.
- Choose an available account login method, complete sign-in with your own Xiaohongshu account, then select Save & Run. Review the results when the task finishes.
Input Parameters
| Parameter | Configuration |
|---|---|
keyword |
Required text. Enter the search keyword; no default is currently configured. Example: LinkFox. Separate multiple terms with spaces; every term must appear in the collected note title, body or tags. Candidate cards must mention at least one term in their title, or have an empty title that requires checking. |
publish_time |
Dropdown; default unlimited. Options: unlimited, one_day, one_week, half_year. |
limit |
Integer, at least 1; default 20. Sets the maximum number of matching notes to return. |
Example Output
An example structured record is shown below. Long text may be shortened for readability. Each returned note occupies its own result and table or CSV row.
| Field | Result |
|---|---|
keyword |
LinkFox |
note_id |
6ae2c51b000000003a020ff8 |
note_url |
https://www.xiaohongshu.com/explore/6ae2c51b000000003a020ff8?xsec_token=AB5jbzACTHWx26c2LP86t3b6U6ntvkiFSPwoHiZ3tOCZc%3D&xsec_source=pc_search |
title |
Linkfox生图真的差 |
body |
生出来图都很丑,并且每次改都要消耗算力,要改很多次才能稍微满意一点,购买的套餐不到一个小时 申请退款还被拒绝,真是无语了 |
note_type |
图文 |
author_nickname |
快乐小马居 |
author_profile_url |
https://www.xiaohongshu.com/user/profile/58ac5f2082ec395fec04d429 |
published_at |
2026-10-29 12:01:31 |
tags |
linkfox, 12315投诉 |
likes |
0 |
collects |
0 |
comments |
0 |
How Does It Work?
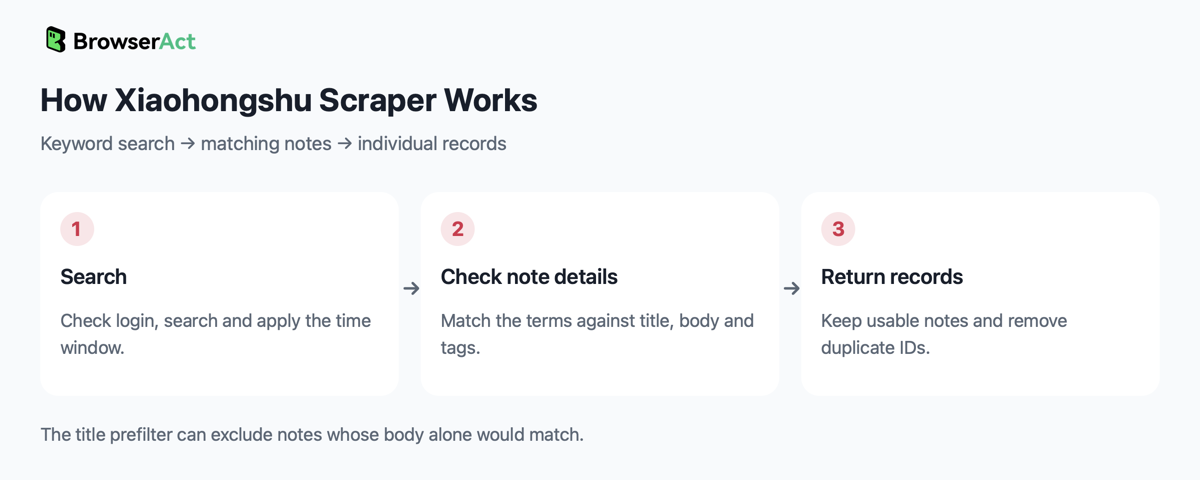
The Bot checks the signed-in account, searches Xiaohongshu and applies the selected time window. It checks eligible note details, verifies the keyword terms against the title, body and tags, removes duplicate note IDs, and returns the matching records. Unreadable notes can be skipped while usable records are retained.
How to Build a New Scraper Bot with Agent Built
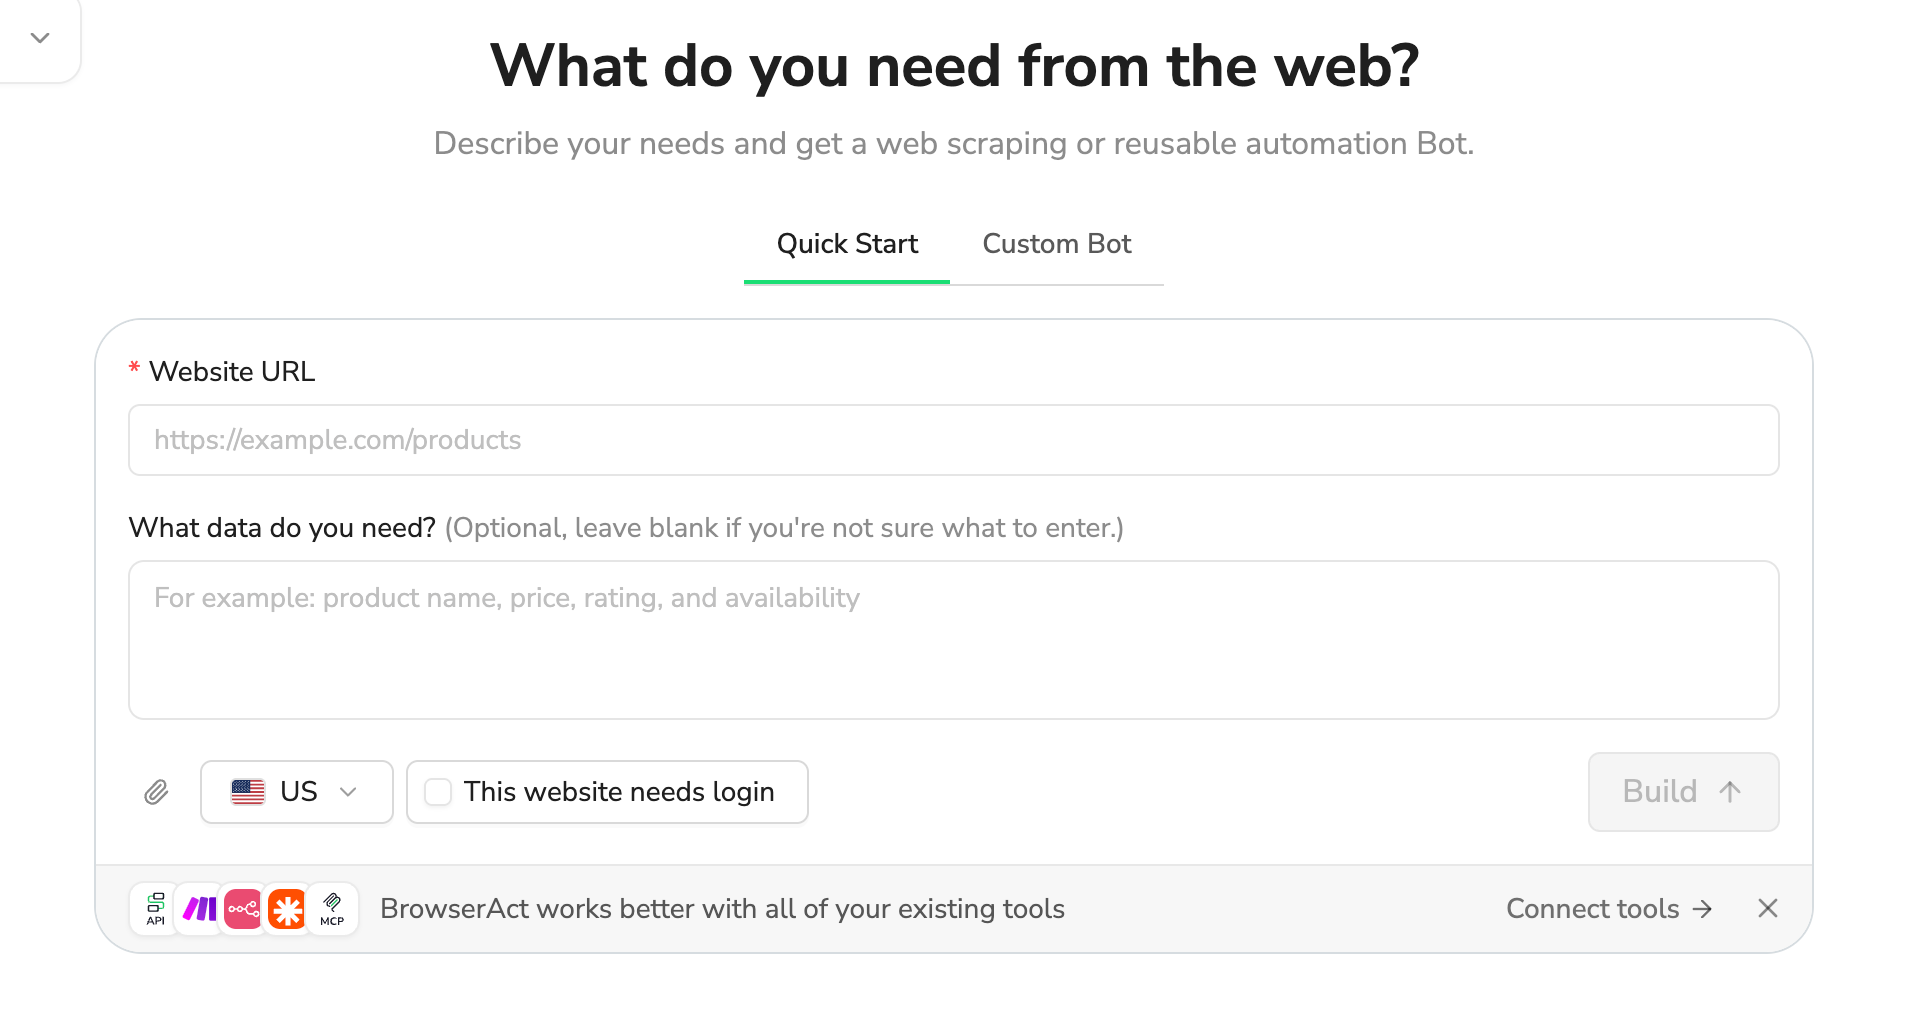
- Describe the website, records and fields you need in BrowserAct.
- Let BrowserAct build and test the Bot; complete your own website login when requested.
- Run the completed Bot and review its structured results.
Why Use Xiaohongshu Notes Scraper?
Use note titles, text and tags to understand how a keyword or brand appears in Xiaohongshu content. Compare creators and engagement counts, collect content examples, and use the source links to review context for campaign or competitor research. Engagement counts alone do not establish sentiment or commercial outcomes.
Who Can Use Xiaohongshu Notes Scraper?
Content marketers, creator-research teams and social-media researchers who have access to their own Xiaohongshu account.
How Many Results Can You Scrape?
The Bot returns up to the requested limit. Matching notes and readable details may be fewer than the requested number. It retains collected notes when some candidates are unreadable. The title prefilter can exclude a note whose title mentions no keyword even when its body would match. Login or access failure is not a successful empty search.
Automation and Export
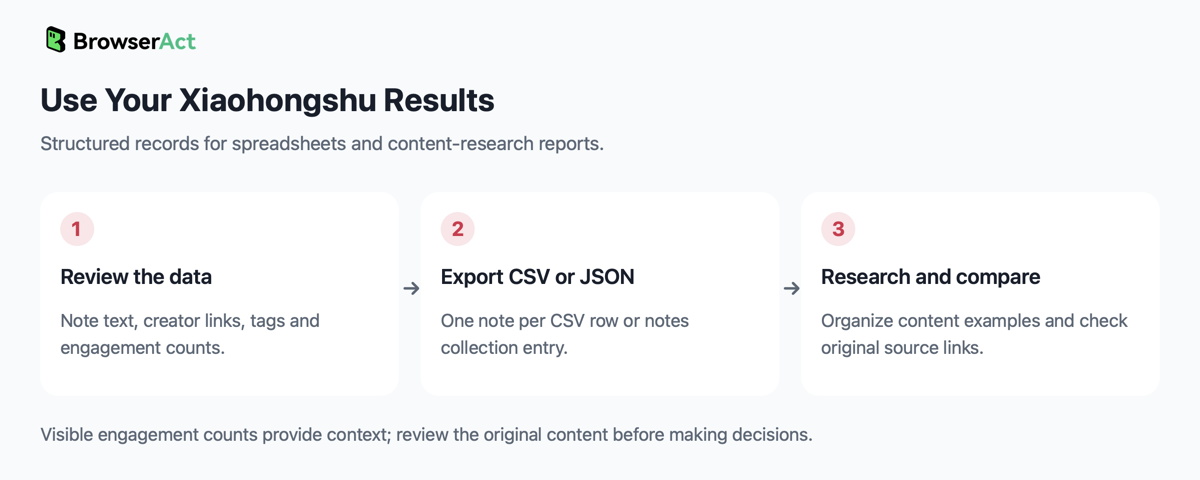
BrowserAct returns structured records that you can review and export as CSV or JSON. The JSON collection is notes, with one note per entry. Use the exported data in spreadsheets and content-research reports.
Need Help?
Need help? Contact live support using the chat button at the bottom right, or email service@browseract.com.
