

What Does BrowserAct Glassdoor Job Details Scraper Do?
Use BrowserAct Glassdoor Job Details Scraper to collect complete public job details from one Glassdoor posting, including job_title, company_name, description, company_rating, salary. The Bot stays within the selected public Glassdoor page flow and returns structured job details for job opportunity analysis, salary and role research, or downstream automation without writing code or requiring a target-site login. Run it in BrowserAct or invoke the same published template through its API Tab.
Key Features of Glassdoor Job Details Scraper
- Configure
job_urlto reuse the same Bot for different public Glassdoor targets. - Collect complete public job details from one Glassdoor posting from the template's defined public page flow.
- Return structured job details with fields such as
job_title,company_name,company_rating,location,workplace_type. - Run without a target-site account login or custom scraper code.
- Use the API Tab to connect the same published template to downstream automation.
What Data Can I Extract from Glassdoor?
| Field | Description |
|---|---|
job_id | Job Id returned from the public Glassdoor page. |
job_title | Visible job title shown on Glassdoor. |
company_name | Visible company name shown on Glassdoor. |
company_rating | Structured company rating extracted from the public source. |
location | Publicly displayed location when available. |
workplace_type | Workplace Type returned from the public Glassdoor page. |
employment_type | Employment Type returned from the public Glassdoor page. |
salary | Structured salary extracted from the public source. |
description | Visible description returned by the public page. |
requirements | Requirements returned from the public Glassdoor page. |
benefits | Benefits returned from the public Glassdoor page. |
employee_estimate | Employee Estimate returned from the public Glassdoor page. |
posted_date | Visible posted date when the source provides it. |
application_deadline | Application Deadline returned from the public Glassdoor page. |
company_logo_url | Public source URL associated with the job details. |
job_url | Public source URL associated with the job details. |
How to Use Glassdoor Job Details Scraper
Quick Start Guide
1. Open Run Task.
2. Review or change the populated input values.
3. Run the Bot.
4. Review the structured result in the Output Tab.
5. Connect the published template to your downstream workflow when needed.
Input Parameters
| Parameter | Configuration |
|---|---|
job_url | String; required; default https://www.glassdoor.com/job-listing/staff-software-engineer-synopsys-JV_KO0%2C23_KE24%2C32.htm?jl=1010228834773. Public job url to process. |
Example Output
The table shows one representative real result. Long text is shortened only in this documentation preview.
| Field | Result | ||
|---|---|---|---|
job_id | 1010228834773 | ||
job_title | Staff Software Engineer | ||
company_name | Synopsys | ||
company_rating | 3.6 | ||
location | Sunnyvale, CA | ||
workplace_type | null | ||
employment_type | null | ||
salary | $138K - $207K (Employer provided) | ||
description | Sunnyvale, California, United States Category Engineering Hire Type Employee Job ID 18309 Base Salary Range $138000-$207000 Date posted 08/11/2026 We Are Synopsys is the leader in engineering solutions from silicon to... | ||
requirements | Education: bachelor's degree \ | Experience: 72 months \ | Skills: Azure, Tooling, Triage, Writing skills, AWS, Release management, JavaScript, Requirements analysis, Scalability, Business requirements, System security, P... |
benefits | Health Insurance, 401K Plan, Vacation & Paid Time Off | ||
employee_estimate | 10000+ Employees | ||
posted_date | 2026-09-12T00:00:00 | ||
application_deadline | 2027-01-12 | ||
company_logo_url | https://media.glassdoor.com/sql/2143/synopsys-squarelogo-1529336950881.png | ||
job_url | https://www.glassdoor.com/job-listing/staff-software-engineer-synopsys-JV_IC1147442_KO0,23_KE24,32.htm?jl=1010228834773 |
How Does It Work?
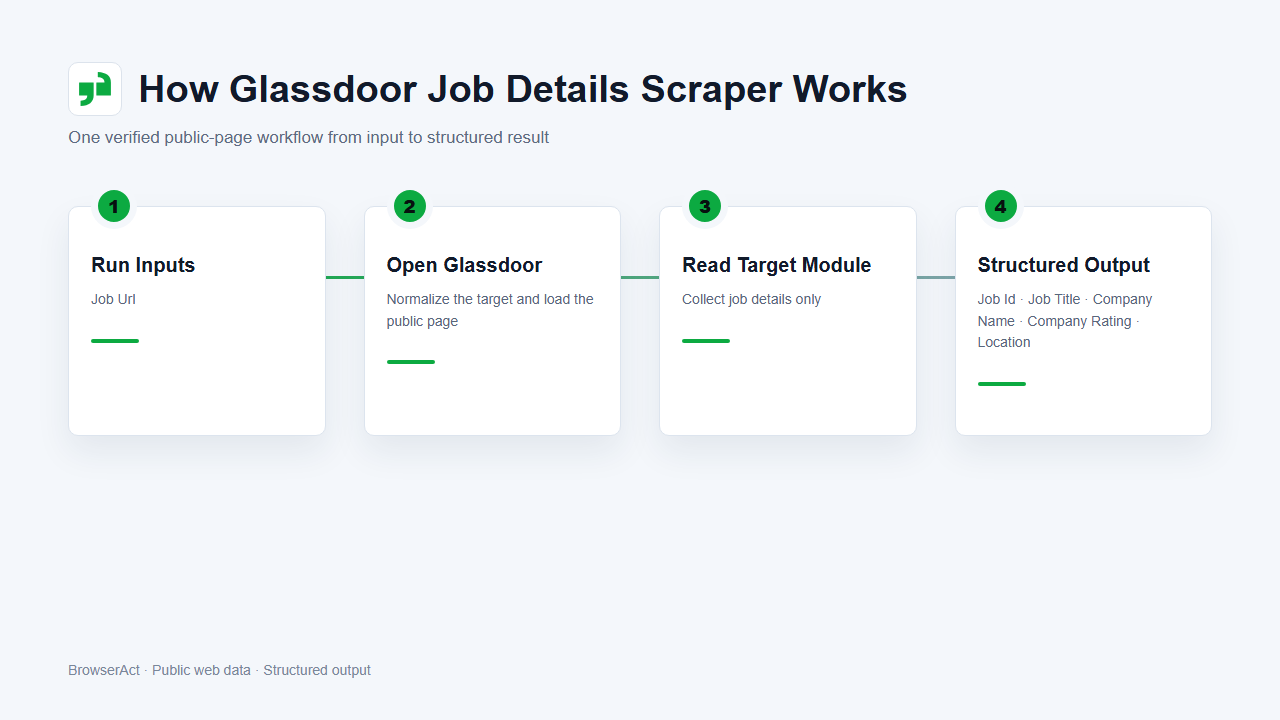
1. BrowserAct validates the supplied inputs and maps supported dropdown selections.
2. The Bot constructs or normalizes the target URL and opens the supplied public detail page.
3. It reads the visible job details without entering unrelated pages or account-only areas.
4. It normalizes visible values, preserves valid optional values, and stops after the target page has been processed.
5. The run returns one structured response for review, export, or downstream automation.
How to Build a New Scraper Bot with Agent Built
Step 1: Describe the data you need
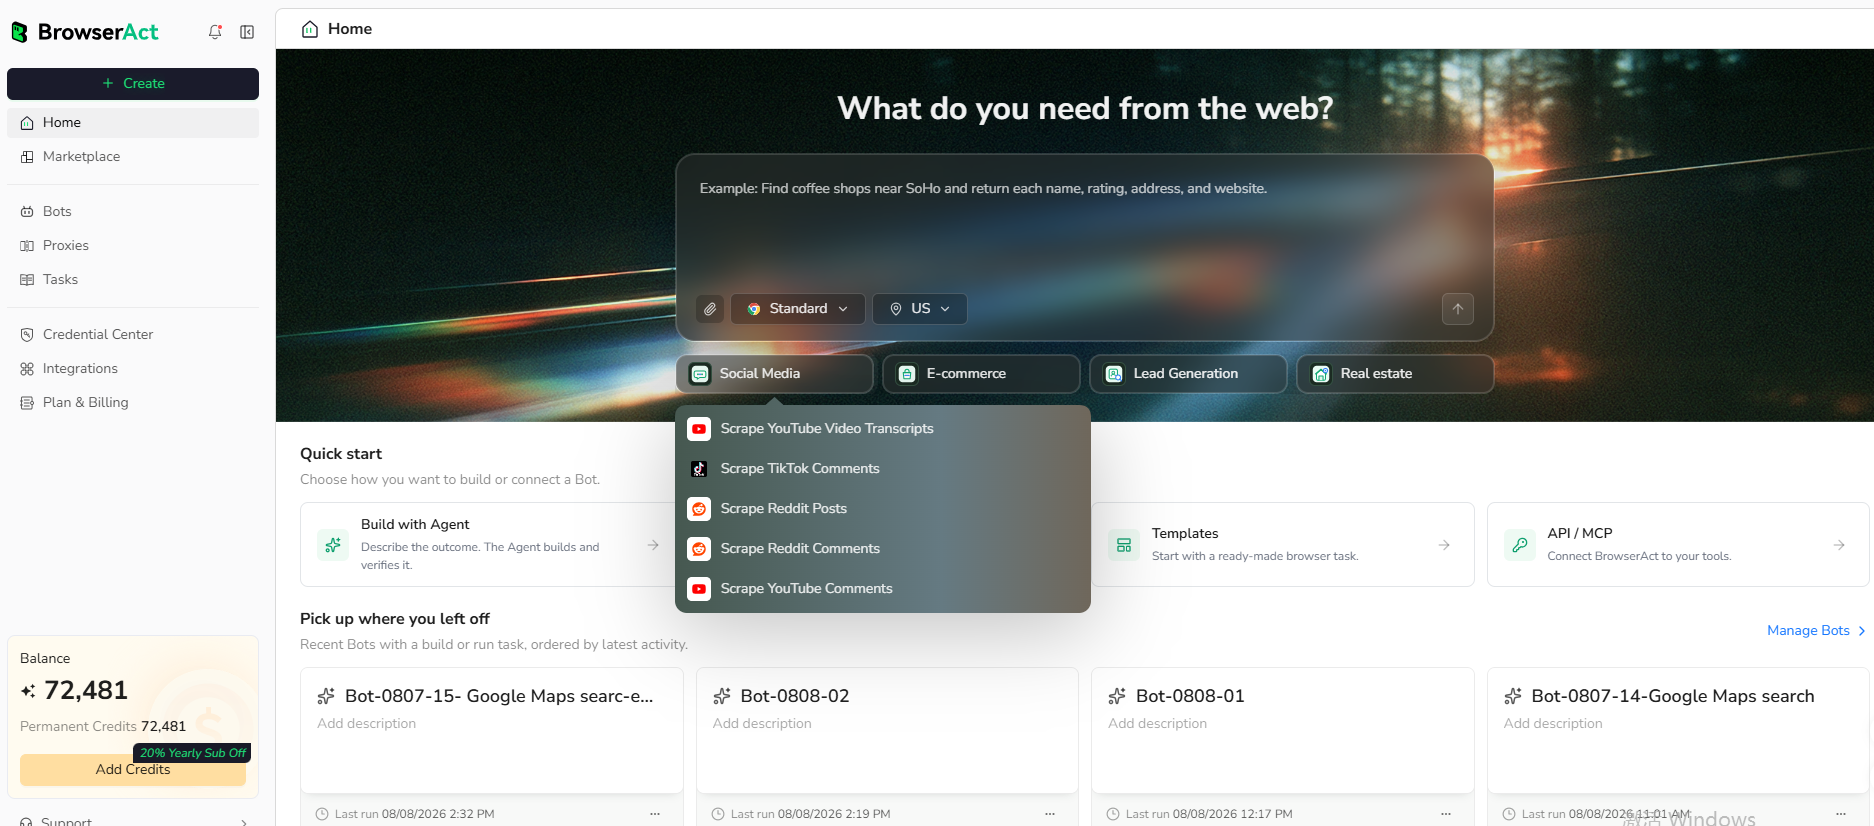
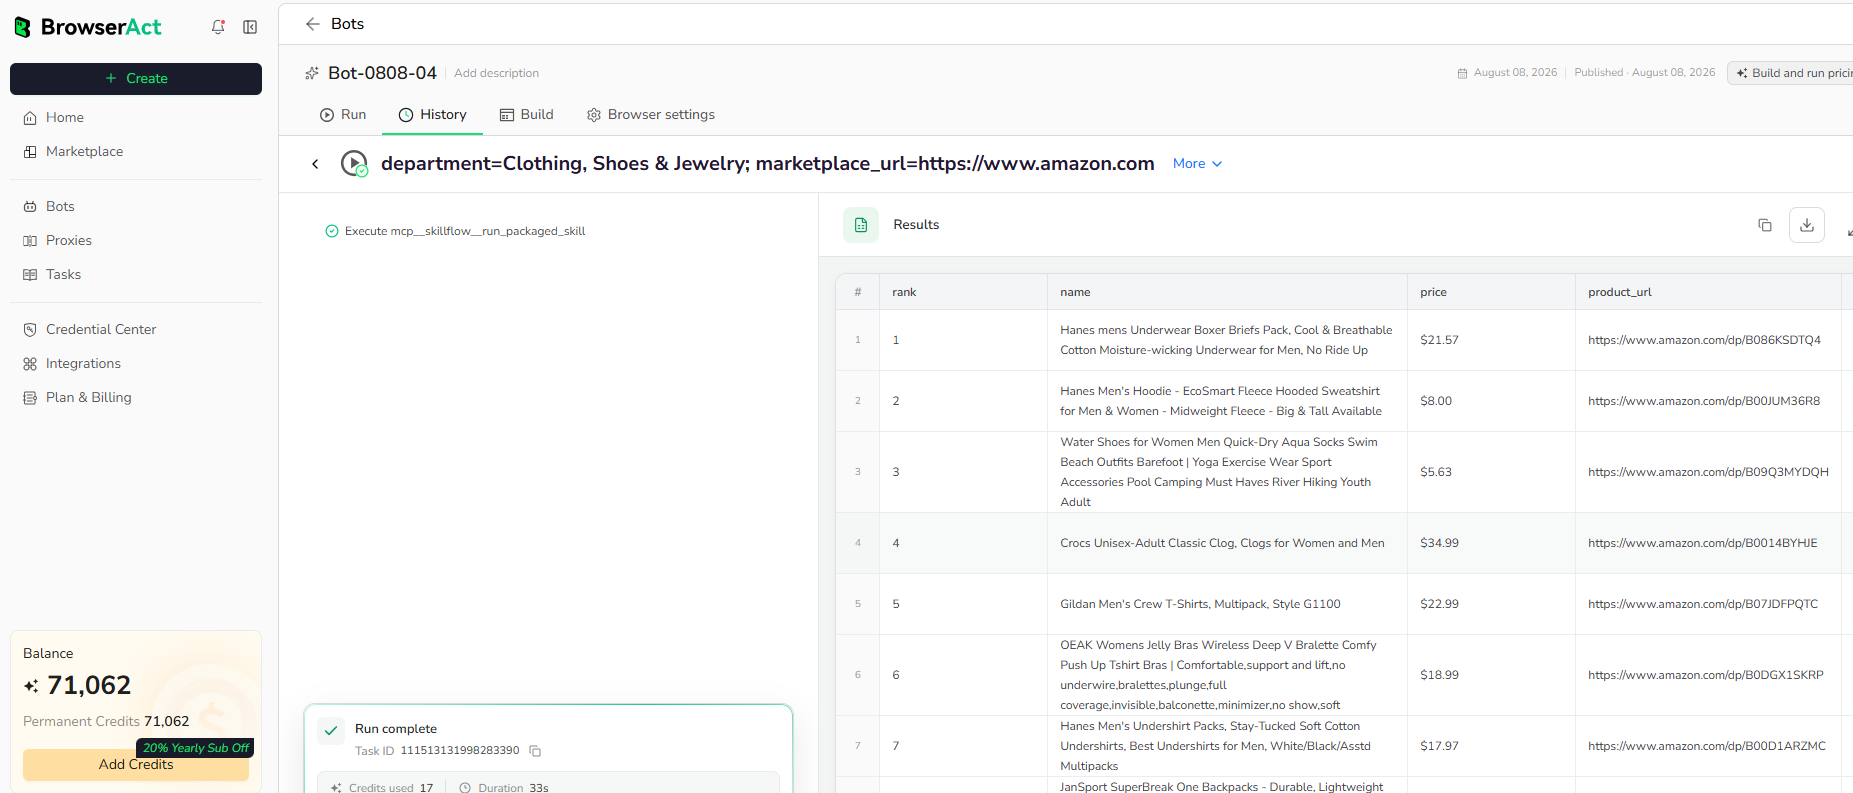
Open BrowserAct and start Agent Built from the Home prompt box or from Create > Build with Agent. Describe the public website, records, filters or search conditions, output fields, result limit, and reusable inputs you need.
Step 2: Let BrowserAct build and test the Bot
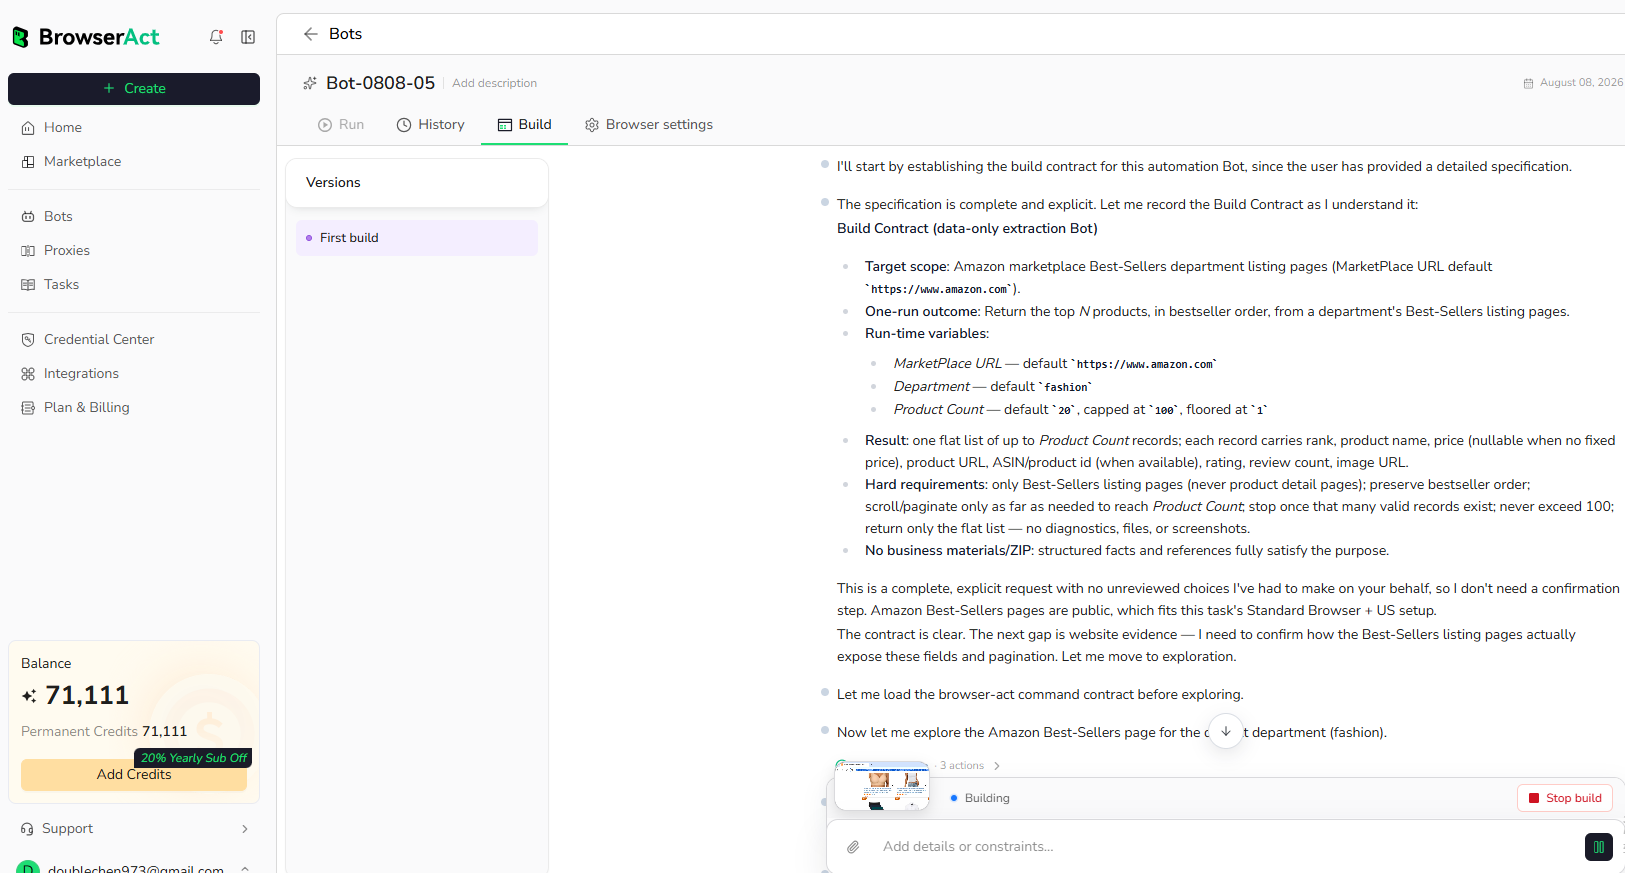
BrowserAct explores the live website, creates the navigation and extraction workflow, and tests the resulting Bot. Provide any requested clarification about the target page, conditions, fields, or expected output in the same build conversation.
Step 3: Run the Bot and review the result
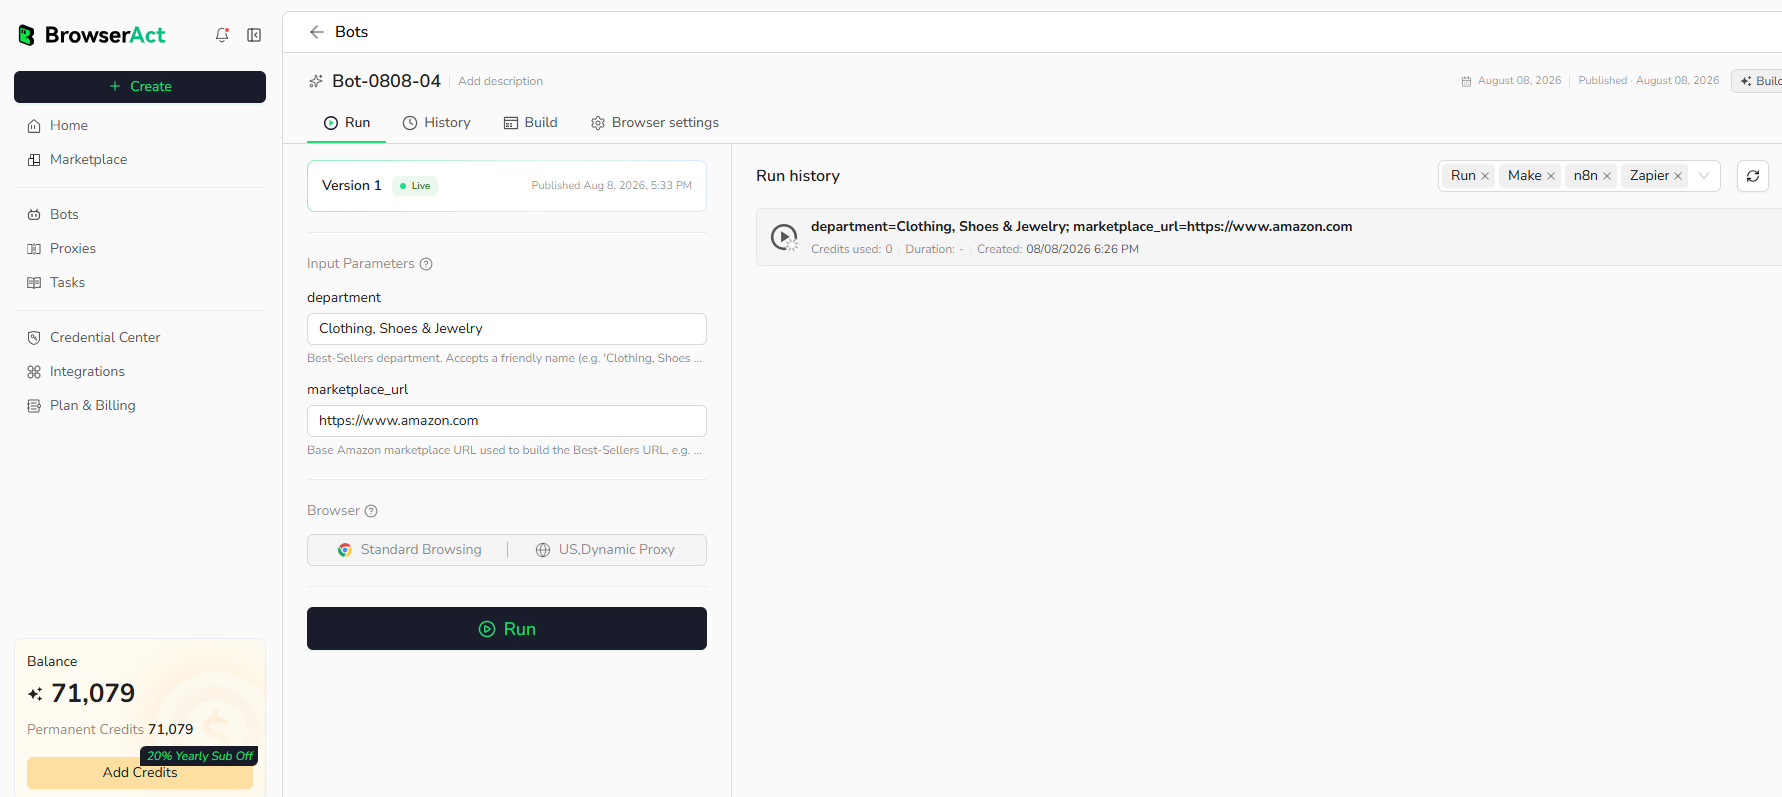
Run the completed Bot with its populated default inputs. Review the structured records, source URLs, missing optional values, and result count before reusing the Bot with other inputs or connecting it to another workflow.
Use Cases
- Job opportunity analysis.
- Salary and role research.
- Recruiting intelligence.
- Connect the structured result to API clients, n8n, Make, Zapier, MCP-based agents, or supported exports.
Why Use Glassdoor Job Details Scraper?
- Reuse a tested public-page workflow instead of configuring the extraction from the beginning.
- Receive structured job details that can move directly into research, review, or automation.
- Change supported inputs without rebuilding the Bot for every run.
Who Can Use Glassdoor Job Details Scraper?
- Teams working on job opportunity analysis.
- Teams working on salary and role research.
- Teams working on recruiting intelligence.
- Developers and automation teams connecting public web data to downstream systems.
How Many Results Can You Scrape?
Each run processes one selected public target and returns one structured result for that target.
Automation and Export
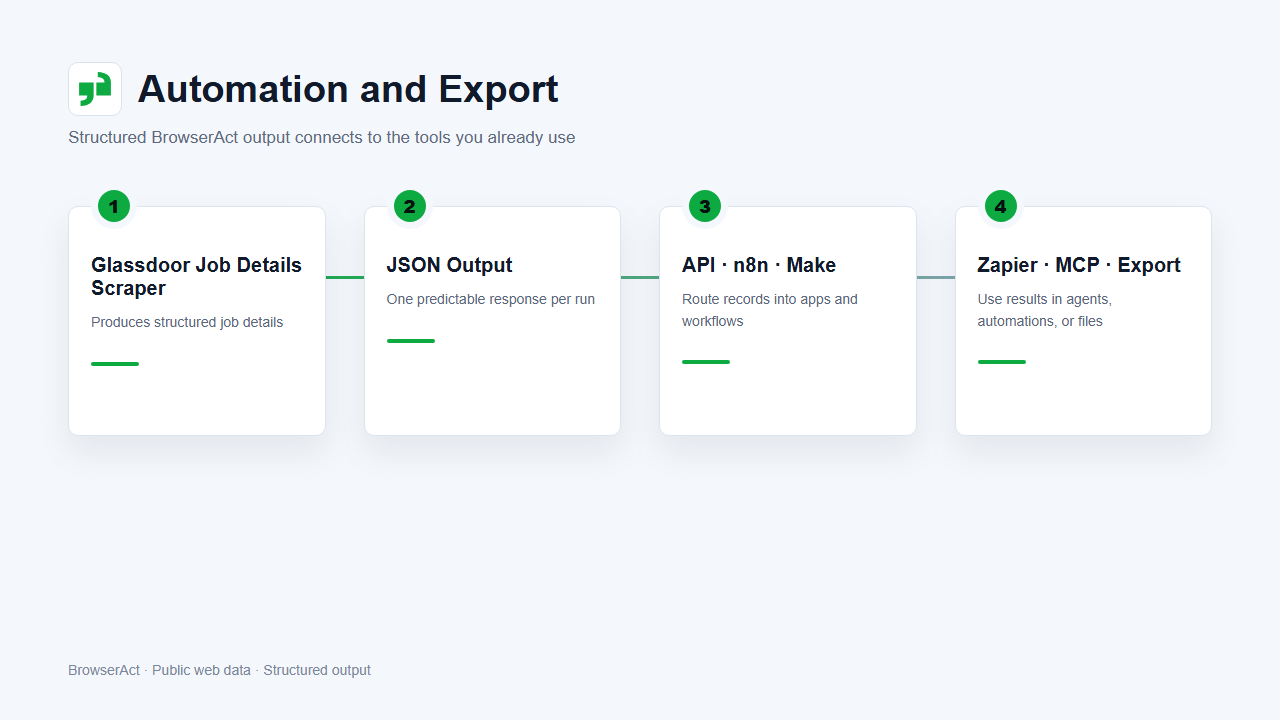
BrowserAct produces structured data first. Use the result through Run Task, the JSON API, n8n, Make, Zapier, MCP-based agents, or the supported manual export flow.
Need Help?
Cannot find the exact capability you need, or need help composing several Bots?
