

Automatically extract visible page text and a full-page PNG from one public URL with our no-code scraper. Capture structured page capture data for website archiving, visual QA, and downstream automation. Configure the request, run the Bot, and receive one predictable structured response without rebuilding the workflow.
What Does BrowserAct Full Page Screenshot Scraper Do?
The Bot extracts visible page text and a full-page PNG from one public URL. It stays within the selected public page flow and returns structured page capture data ready for review or automation.
Key Features
- Reads public Public Web data without requiring an account login.
- Uses non-empty defaults so the template can run immediately.
- Maps finite website options to dropdown inputs when available.
- Returns structured values from the selected capability only.
- Keeps conditional values empty only when the public page does not display them.
Quick Start
1. Open Run Task.
2. Review or change the populated input values.
3. Run the Bot.
4. Review the structured result in the Output Tab.
5. Connect the published template to your downstream workflow when needed.
Input Parameters
| Parameter | Configuration |
|---|---|
page_url | String; required; default https://example.com/. Public page url to process. |
Example Output
The table shows one representative real result. Long text is shortened only in this documentation preview.
| Field | Result |
|---|---|
page_title | Example Domain |
meta_description | null |
language | en |
visible_text | Example Domain This domain is for use in documentation examples without needing permission. Avoid use in operations. Learn more |
captured_at | 2026-09-14T11:57:00Z |
screenshot_file | full-page-screenshot.png |
How Does It Work?
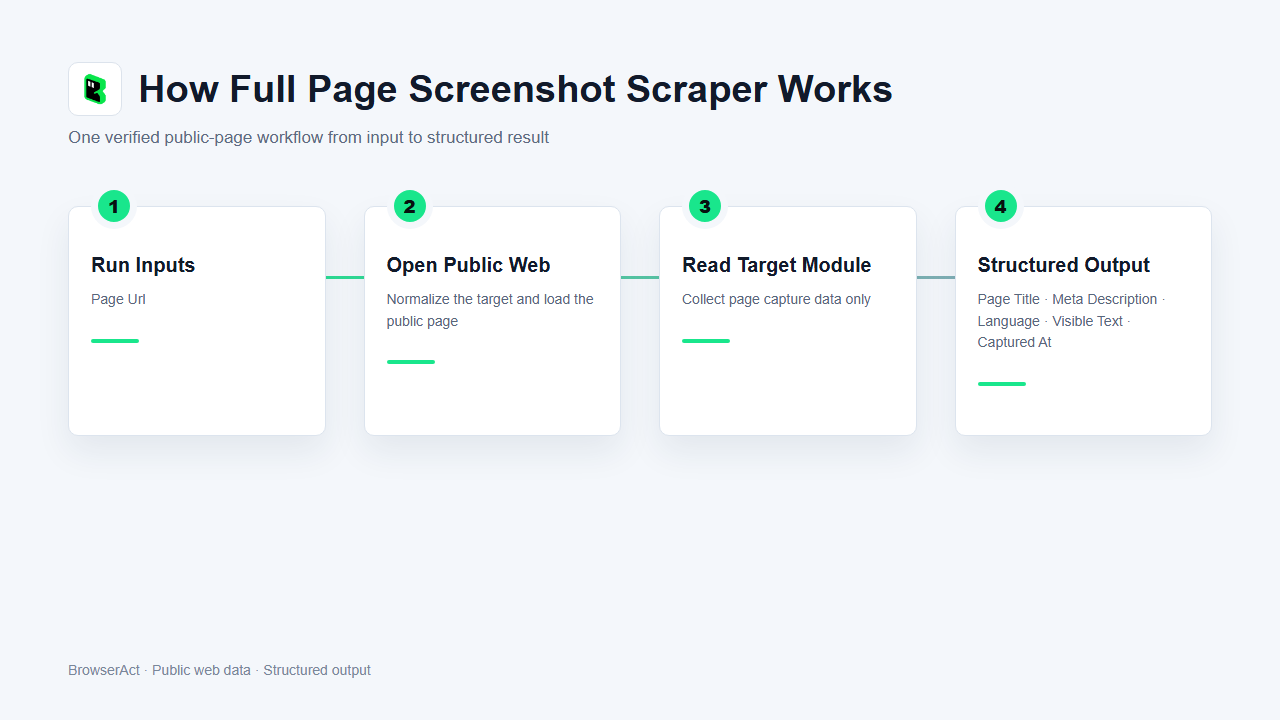
1. BrowserAct validates the supplied inputs and maps supported dropdown selections.
2. The Bot constructs or normalizes the target URL and opens the supplied public detail page.
3. It reads the visible page capture data without entering unrelated pages or account-only areas.
4. It normalizes visible values, preserves valid optional values, and stops after the target page has been processed.
5. The run returns one structured response for review, export, or downstream automation.
Use Cases
- Website archiving.
- Visual QA.
- Page content collection.
- Connect the structured result to API clients, n8n, Make, Zapier, MCP-based agents, or supported exports.
Create Your Own Full Page Screenshot Scraper
Step 1: Create an Editable Copy
Click Create Editable Duplicate in the upper-right corner of this page. An editable copy will be added to your BrowserAct workspace.
Step 2: Customize the Bot When Needed
Open the duplicate from your Bots list. Use Improve only when you need to change inputs, extraction behavior, or output fields. If the current workflow already fits, use it as is and find its Bot ID in the Bots list.
Step 3: Run the Bot Through the API
Use the Bot ID with the BrowserAct API to invoke your workflow programmatically and retrieve structured results in your application.
Automation and Export
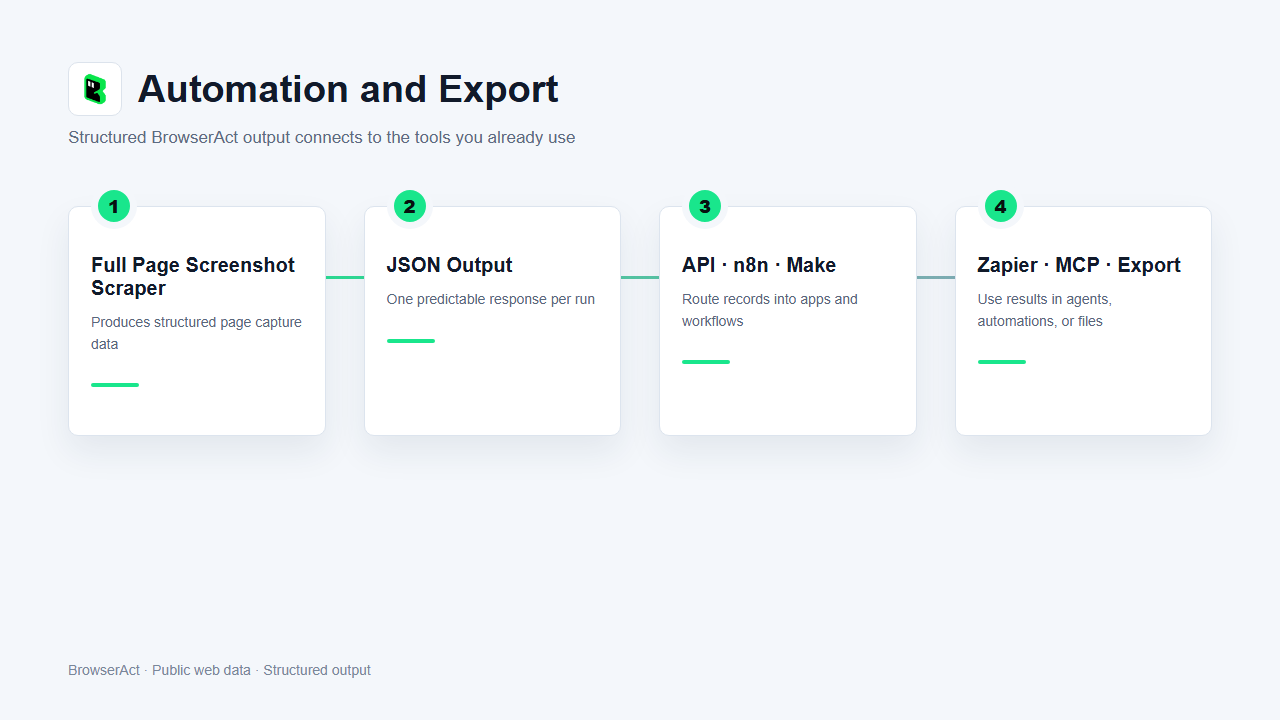
BrowserAct produces structured data first. Use the result through Run Task, the JSON API, n8n, Make, Zapier, MCP-based agents, or the supported manual export flow.
Need Help?
Cannot find the exact capability you need, or need help composing several Bots?
