
Scraping GitHub Users Activity & Data (Based on Source Top GitHub Contributors by Language & Location)
BrowserAct’s no-code tool scrapes GitHub users’ activity & data by language/location—targets top contributors, extracts key details fast for devs/recruiters!
Published by
Yi
Yiruo
December 22, 2025
Approx.Credits
150-200 Credits
Categories
BA
Content CollectionGitHub
Template ID
60028936641509008

Brief
Are you spending hours manually collecting GitHub search data—queries, results, repository details, user profiles, code snippets, and more? With millions of repositories, projects, and open-source contributions to browse through, finding the right data or conducting research has become incredibly time-consuming for developers, researchers, analysts, and open-source enthusiasts.
BrowserAct automates the entire process. Extract structured data from GitHub in minutes, not hours—no coding required.
What Does BrowserAct GitHub Scraper Do?
Automatically extract comprehensive GitHub resource data with our powerful GitHub scraper tool. Capture repository names, descriptions, owner details, star counts, fork counts, programming languages, last updated times, and links to repositories from any GitHub search page. Enjoy flexible filtering and output options for comprehensive market analysis—no coding required.
Our GitHub scraper is built for seamless integration with automation platforms like Make.com, making it ideal for ongoing monitoring and competitive intelligence tasks.
What Data Can I Extract from GitHub?
With BrowserAct's GitHub Scraper, you can pull a wide range of publicly available data for analysis. Here's a breakdown:
GitHub Search Results & Features
- Repository names
- Descriptions and summaries
- Owner usernames and profiles
- Star counts
- Fork counts
- Programming languages
- Last updated dates
- URLs and links to repositories
Key Features of GitHub Scraper
- Customizable Parameters: Adjust extraction scope to match your research needs
- Flexible Selection: Set max items for bulk extraction across multiple pages
- Comprehensive Data Capture: Extracts complete search profiles with all metadata
- Structured Output: Preserves data relationships for easy analysis
- Multi-Page Support: Compatible with search results, repository listings, and user profiles
- Automation-Ready: Seamlessly integrates with Make.com and other platforms
How to Scrape GitHub
Quick Start Guide: How to Use GitHub Scraper in One Click
If you want to quickly start experiencing scraping GitHub, simply use our pre-built "GitHub Scraper" template for instant setup and start scraping GitHub effortlessly.
- Register Account: Create a free BrowserAct account using your email
- Configure Parameters: Fill in necessary inputs like Target_url (e.g., "https://github.com/search?q=example") – or use defaults to learn how to scrape GitHub quickly
- Start Execution: Click "Start" to run the workflow
- Download Data: Once complete, download the results file from GitHub scraping
How to Build a GitHub Scraper Workflow: Step by Step
GitHub Scraper workflow building with BrowserAct requires no coding skills—it's automation-ready and easy to set up. Follow these step-by-step instructions to get started.
- Determine Your Scope
Decide the number of results to extract (e.g., 50 results with complete details). Adjust parameters based on your research needs.
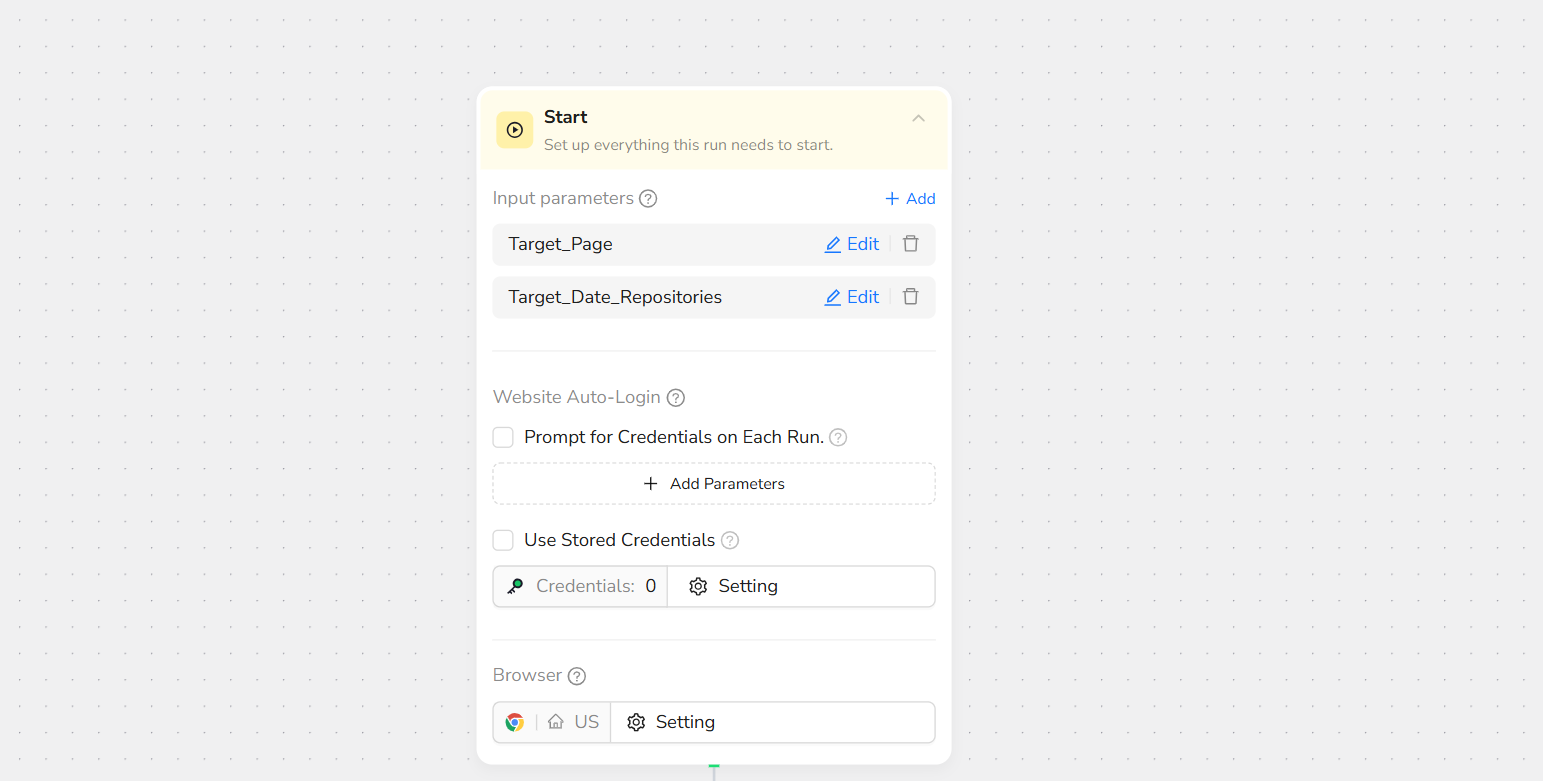
- Start Node Parameter Settings
- Target_Page: Enter your GitHub link (e.g., https://github.com/search?)
Note: Customize based on needs—works with search results, repository listings, or user profiles.
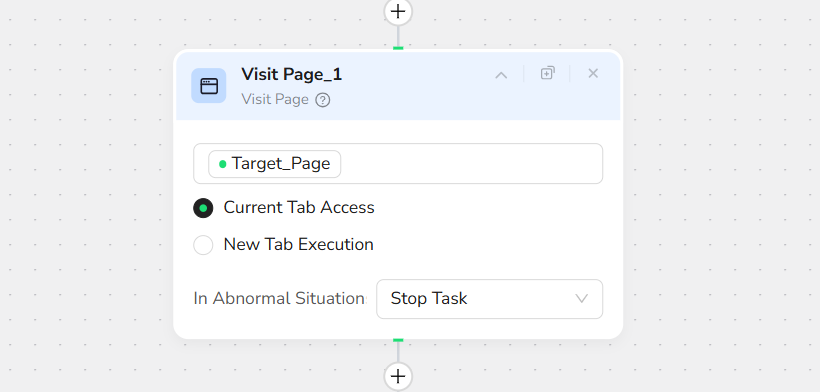
- Visit Page
In the prompt box, enter Visit / Target_Page – this will navigate to the target URL.
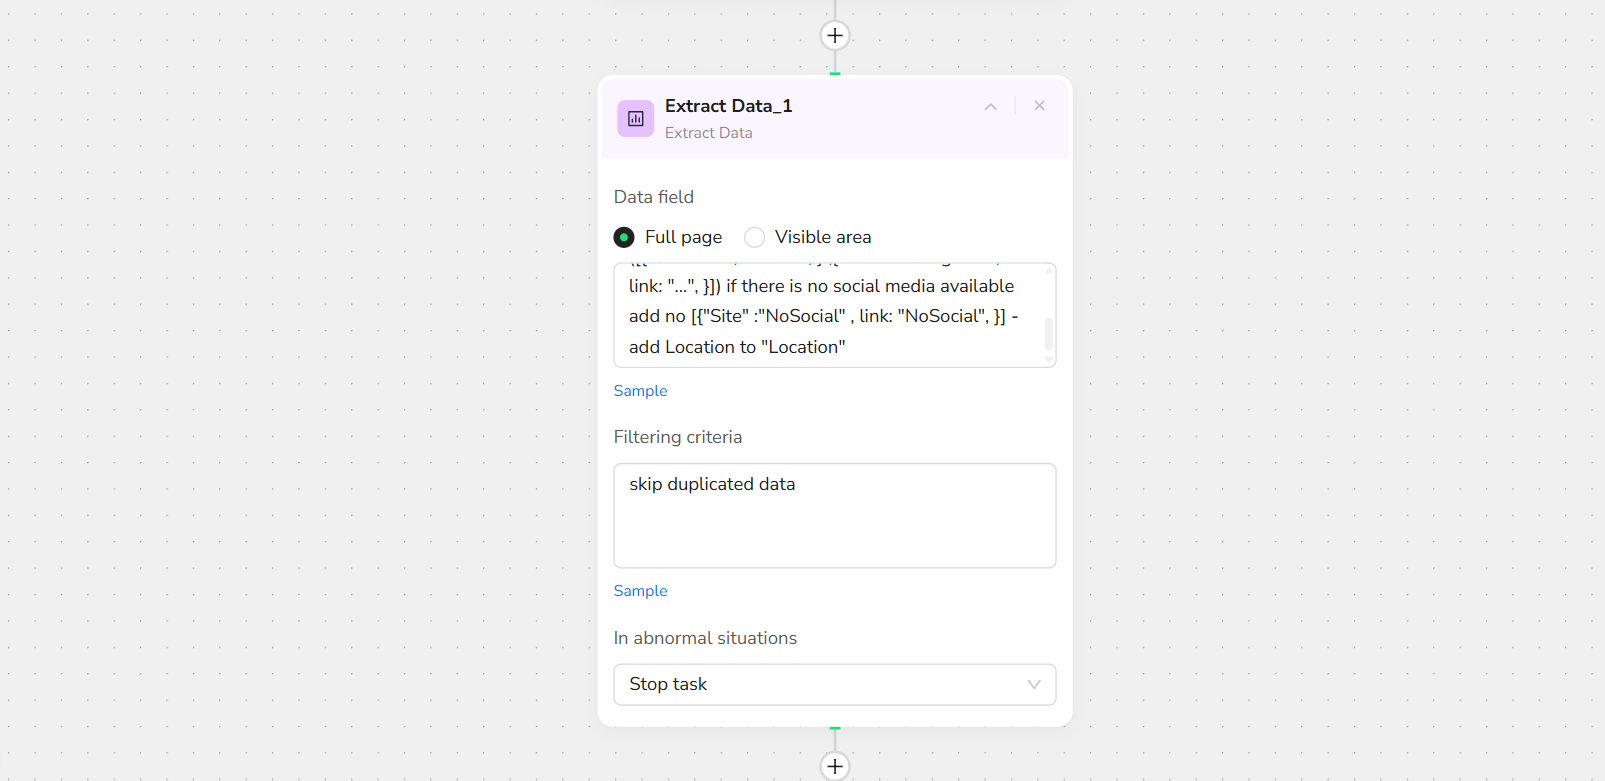
- Add Extract Data
In the prompt box, enter:
Extract the user data
- Summarize page resume if he had and add to "Summary"
- add connection links to "Links" as list of maps ([{"Site" :"X" , link: "...", } ,{"Site" :"Instagram" , link: "...", }])
if there is no social media available add no [{"Site" :"NoSocial" , link: "NoSocial", }]
- add Location to "Location"
Note: You can specify the exact location of the data to be collected on the page to increase the accuracy of data extraction.
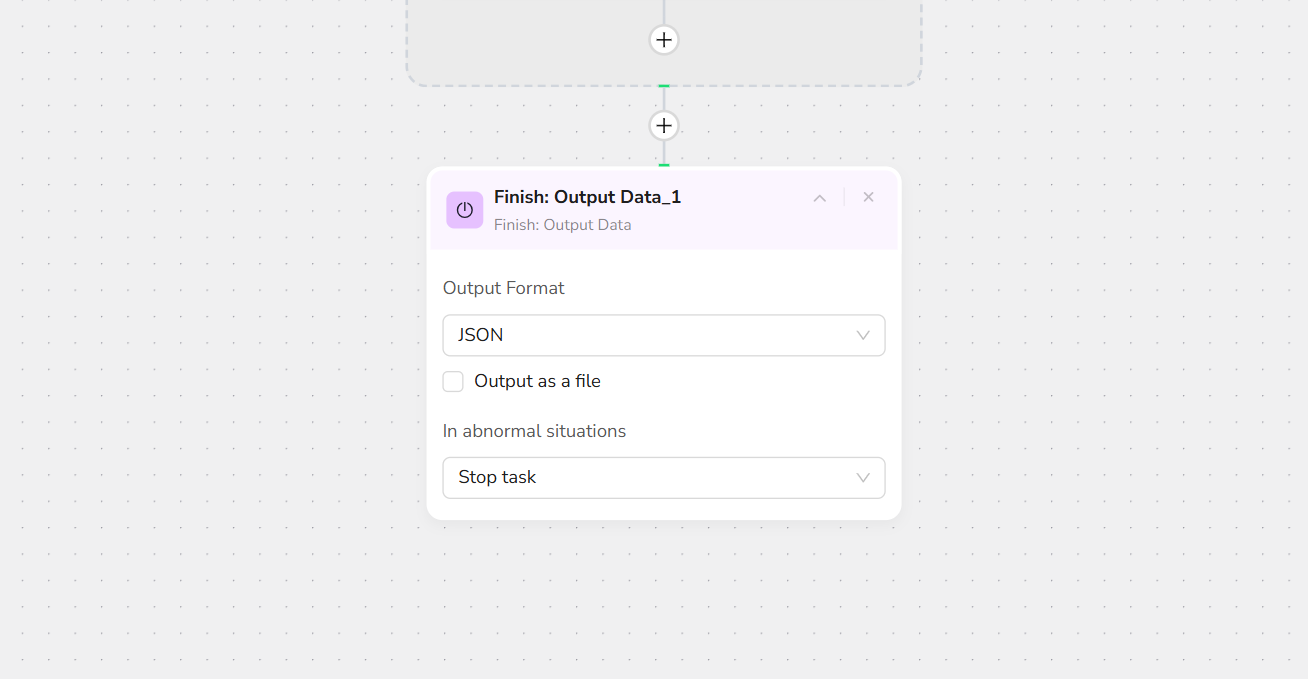
- Output Data
Export in JSON, CSV, XML, or Excel formats.
Key Benefits of GitHub Scraper
GitHub Scraper offers a range of advantages that make data extraction simple, efficient, and powerful. Here's why it's a top choice for GitHub web scraping:
✅ No Coding Required: Set up and run extractions effortlessly without any programming skills—perfect for beginners and pros alike
✅ Customizable and Flexible: Adjust parameters like item limits, data fields, and target URLs to tailor results to your exact needs
✅ Structured Data Output: Maintains organized data in structured formats (e.g., JSON, CSV, Excel) for easy analysis and integration
✅ Automation Integration: Seamlessly works with Make, n8n, and other platforms for scheduled, hands-off web scraping
✅ Cost-Effective: Start with free trials for small-scale tasks, scaling affordably for larger datasets while respecting GitHub's policies
✅ Accurate and Reliable: Handles automatic page loading, uses 'N/A' for missing data, and includes rate limit handling to ensure consistent results
These benefits make GitHub Scraper an efficient tool for turning raw GitHub data into actionable insights.
Who Can Use GitHub Scraper?
GitHub Scraper is designed for anyone needing quick, reliable access to GitHub data. It's ideal for a variety of users, including:
- Developers & Engineers: Discover trending repos and open-source libraries
- Tech Recruiters & Talent Scouts: Analyze contributor profiles and project activity
- Open-Source Maintainers: Conduct competitive analysis and track ecosystem trends
- Digital Agencies: Manage client tech stack recommendations with comprehensive repo data
- Market Researchers & Analysts: Extract data for trend analysis and market intelligence
- Product Managers: Gather insights on features, adoption, and community engagement
- Small Teams & Startups: Conduct affordable competitive research without needing advanced technical skills
- Academics & Students: Research code trends and open-source ecosystems
No matter your background, if you're looking to scrape GitHub without hassle, this tool is accessible and effective for both individuals and teams.
Use Cases for GitHub Scraper
GitHub Scraper is versatile for various real-world applications. Here are some key ways to use it for extracting and analyzing GitHub data:
📊 Market Research: Collect data on trending repositories, languages, and topics for informed decision-making
🔍 Competitive Intelligence: Scrape competitor repos to identify strengths, weaknesses, and innovation opportunities
💰 Pricing Analysis: Track open-source alternatives and compare features across similar projects
⭐ Quality Assessment: Analyze stars, forks, and contributor activity to identify top-rated solutions
🔄 Update Monitoring: Track commit frequency and release patterns
🛠️ Library Selection: Build comprehensive comparison databases to select the best tools for your projects
📈 Trend Tracking: Monitor emerging frameworks and popular categories in the GitHub ecosystem
🎯 Talent Research: Identify active contributors and assess their portfolios
Whether for one-off projects or ongoing monitoring, GitHub Scraper helps transform GitHub data into valuable insights.
Make.com Integration
BrowserAct's GitHub Scraper is now available as a native app on Make.com—add it to your scenarios without API hassle.
✅ Automation-Ready: Integrate with Make, n8n, or others for scheduled monitoring
✅ Rate Limit Handling: Built-in delays to comply with GitHub policies
✅ Multi-Category Tracking: Run instances for different search queries, languages, or topics
💡 Use Case Tip: Ideal for competitive analysis, trend tracking, and market research with complete repository metadata
🚀 Quick Start with Make.com: Search for "BrowserAct" in Make.com's app directory and add it directly—no complex setup
Ready to Transform Your GitHub Data Collection?
Stop wasting hours on manual data collection. Start scraping GitHub repositories, users, and trends in minutes with BrowserAct's AI-powered automation.
Try BrowserAct Free → https://www.browseract.com/
No credit card required. Get started in under 5 minutes.
Popular Use Cases:
- 🛍️ Developers finding trending libraries
- 💻 Recruiters analyzing contributor activity
- 📊 Analysts tracking open-source trends
- 🏢 Teams managing tech stack recommendations
- 🚀 Startups performing competitive analysis
Start Your Free Trial → https://www.browseract.com/template?page=3
Need Help?
Contact us at:
- 📧 Discord: https://discord.com/invite/UpnCKd7GaU
- 💬 E-mail: service@browseract.com
 What can we do for you