
Monitor Viral Topics on Reddit and Get Real-Time Alerts on Telegram
BrowserAct monitors viral topics on Reddit—no code needed, captures trending content in real time and sends instant alerts to your Telegram for timely insights!
Published by
Yi
Yiruo
December 19, 2025
Approx.Credits
20-50 Credits
Categories
BA
Content CollectionReddit
Template ID
61670605683951264

Brief
Are you spending hours manually collecting Reddit data—communities, posts, comments, upvotes, users, and more? With thousands of communities, endless conversations, and authentic human connection to browse through, finding the right data or conducting research has become incredibly time-consuming for researchers, marketers, analysts, and community managers.
BrowserAct automates the entire process. Extract structured data from Reddit in minutes, not hours—no coding required.
What Does BrowserAct Reddit Scraper Do?
Automatically extract comprehensive Reddit resource data with our powerful Reddit scraper tool. Capture post titles, content, comment counts, upvote scores, user names, subreddit details, timestamps, and links to threads from any Reddit page. Enjoy flexible filtering and output options for comprehensive market analysis—no coding required.
Our Reddit scraper is built for seamless integration with automation platforms like Make.com, making it ideal for ongoing monitoring and competitive intelligence tasks.
What Data Can I Extract from Reddit?
With BrowserAct's Reddit Scraper, you can pull a wide range of publicly available data for analysis. Here's a breakdown:
Reddit Communities & Features
- Post titles
- Content (stories, links, images, videos)
- Comment counts
- Upvote/downvote scores
- User names
- Subreddit names
- Timestamps
- Links to posts and communities
Key Features of Reddit Scraper
- Customizable Parameters: Adjust extraction scope to match your research needs
- Flexible Selection: Set max items for bulk extraction across multiple pages
- Comprehensive Data Capture: Extracts complete post profiles with all metadata
- Structured Output: Preserves data relationships for easy analysis
- Multi-Page Support: Compatible with subreddit listings, search results, and thread pages
- Automation-Ready: Seamlessly integrates with Make.com and other platforms
How to Scrape Reddit
Quick Start Guide: How to Use Reddit Scraper in One Click
If you want to quickly start experiencing scraping Reddit, simply use our pre-built "Reddit Scraper" template for instant setup and start scraping Reddit effortlessly.
- Register Account: Create a free BrowserAct account using your email
- Configure Parameters: Fill in necessary inputs like Target_url (e.g., "https://www.reddit.com/search?q=example") – or use defaults to learn how to scrape Reddit quickly
- Start Execution: Click "Start" to run the workflow
- Download Data: Once complete, download the results file from Reddit scraping
How to Build a Reddit Scraper Workflow: Step by Step
Reddit Scraper workflow building with BrowserAct requires no coding skills—it's automation-ready and easy to set up. Follow these step-by-step instructions to get started.
- Determine Your Scope
Decide the number of results to extract (e.g., 50 results with complete details). Adjust parameters based on your research needs.
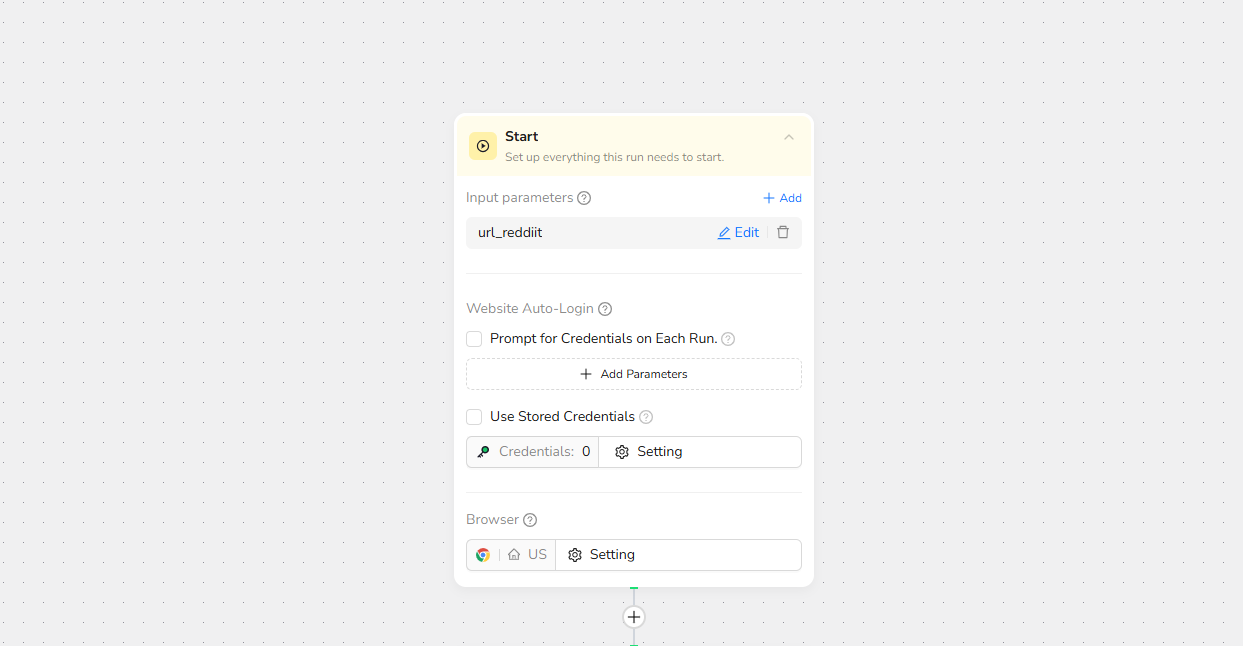
- Start Node Parameter Settings
- url_reddit: Enter your Reddit link (e.g., https://www.reddit.com/)
Note: Customize based on needs—works with subreddit listings, search results, and thread pages.
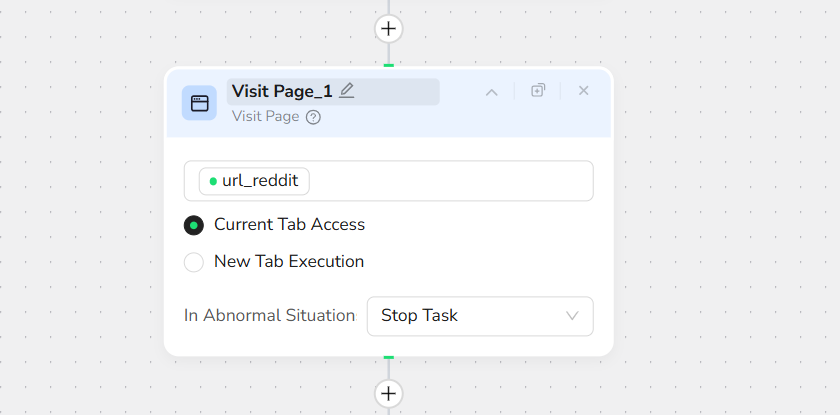
- Visit Page
In the prompt box, enter Visit / url_reddit – this will navigate to the target URL.
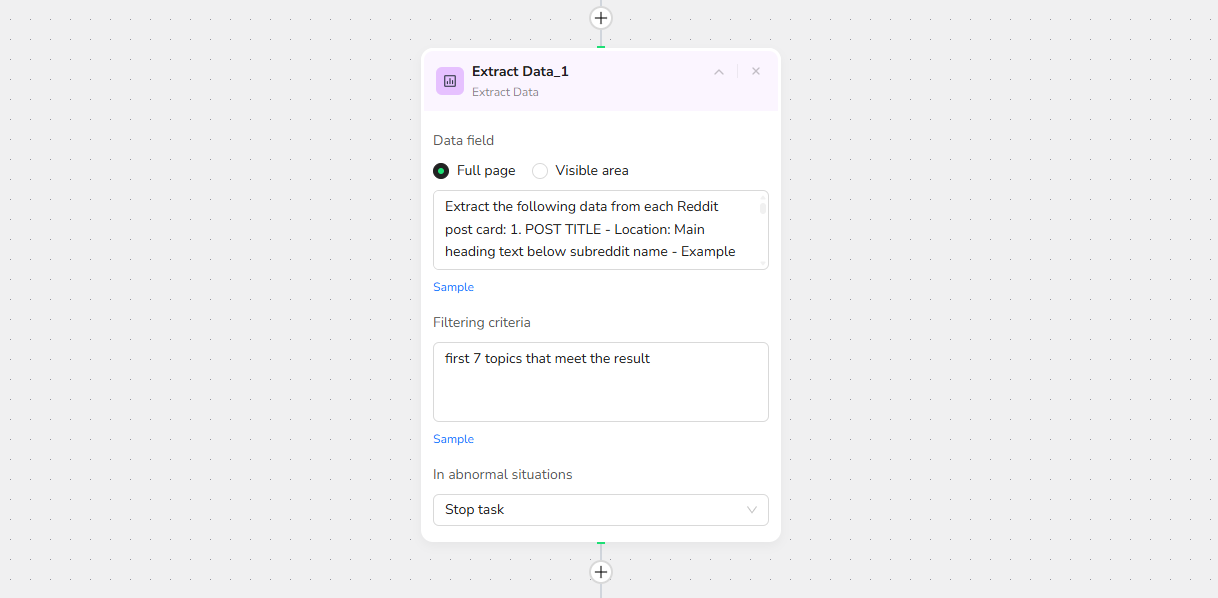
- Add Extract Data
In the prompt box, enter:
Extract the following data from each Reddit post card:
1. POST TITLE
- Location: Main heading text below subreddit name
- Example from image: "Frenly soluciona el dumping de tokens con herramientas de distribución más inteligentes"
- Full text including all lines

2. UPVOTES/SCORE
- Location: Left side, number with up arrow (↑)
- Example from image: "255"
- Extract only the numeric value

3. NUMBER OF COMMENTS
- Location: Comment icon with number
- Example from image: "2"
- Extract only the numeric value

4. TIME POSTED
- Location: Top right, next to subreddit name
- Example from image: "hace 2 h" (2 hours ago)
- Keep original format or convert to "X hours ago" / "X minutes ago"

5. SUBREDDIT
- Location: Top left with "r/" prefix
- Example from image: "r/CryptoMoonShots"
- Include the "r/" prefix

6. POST URL
- Location: Click target of the entire post or title link
- Should be full Reddit URL: https://reddit.com/r/[subreddit]/comments/[post_id]/
- Make it clickable link

7. AUTHOR (Optional)
- Location: Usually near time stamp
- Format: "u/username"

8. AWARDS (Optional)
- Location: Near score/comments area
- Count total awards if present
- Indicates high engagement
Note: You can specify the exact location of the data to be collected on the page to increase the accuracy of data extraction.
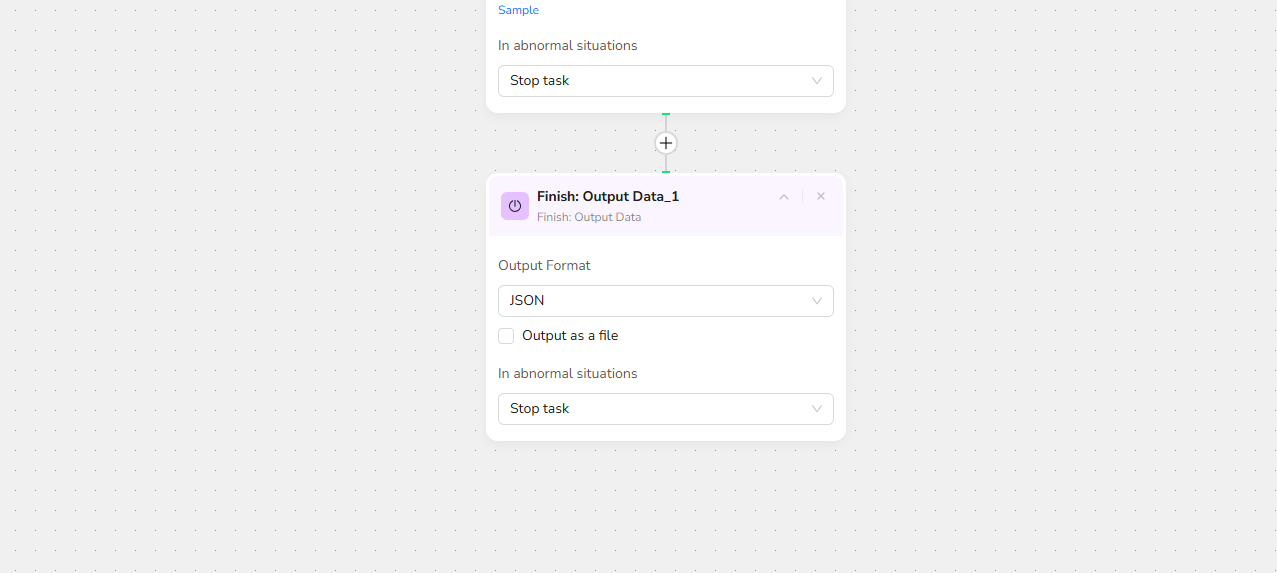
- Output Data
Export in JSON, CSV, XML, or Excel formats.
Key Benefits of Reddit Scraper
Reddit Scraper offers a range of advantages that make data extraction simple, efficient, and powerful. Here's why it's a top choice for Reddit web scraping:
✅ No Coding Required: Set up and run extractions effortlessly without any programming skills—perfect for beginners and pros alike
✅ Customizable and Flexible: Adjust parameters like item limits, data fields, and target URLs to tailor results to your exact needs
✅ Structured Data Output: Maintains organized data in structured formats (e.g., JSON, CSV, Excel) for easy analysis and integration
✅ Automation Integration: Seamlessly works with Make, n8n, and other platforms for scheduled, hands-off web scraping
✅ Cost-Effective: Start with free trials for small-scale tasks, scaling affordably for larger datasets while respecting Reddit's policies
✅ Accurate and Reliable: Handles automatic page loading, uses 'N/A' for missing data, and includes rate limit handling to ensure consistent results
These benefits make Reddit Scraper an efficient tool for turning raw Reddit data into actionable insights.
Who Can Use Reddit Scraper?
Reddit Scraper is designed for anyone needing quick, reliable access to Reddit data. It's ideal for a variety of users, including:
- Researchers & Analysts: Find the perfect discussions and trends for your studies
- Marketers & SEO Specialists: Analyze community sentiment and identify gaps in the social ecosystem
- Developers & Content Creators: Conduct competitive analysis and track viral strategies
- Digital Agencies: Manage client recommendations with comprehensive forum data
- Market Researchers & Analysts: Extract data for trend analysis and market intelligence
- Product Managers: Gather insights on user feedback, features, and community satisfaction
- Small Businesses & Startups: Conduct affordable competitive research without needing advanced technical skills
- Academics & Students: Research social trends and discussion ecosystems
No matter your background, if you're looking to scrape Reddit without hassle, this tool is accessible and effective for both individuals and teams.
Use Cases for Reddit Scraper
Reddit Scraper is versatile for various real-world applications. Here are some key ways to use it for extracting and analyzing Reddit data:
📊 Market Research: Collect data on subreddit discussions, trends, and user queries for informed decision-making
🔍 Competitive Intelligence: Scrape competitor subreddit details to identify strengths, weaknesses, and market opportunities
💰 Pricing Analysis: Track pricing discussions and compare feedback across similar products/services
⭐ Quality Assessment: Analyze user upvotes and comments to identify top-rated ideas
🔄 Update Monitoring: Track post update frequencies and community patterns
🛠️ Topic Selection: Build comprehensive comparison databases to select the best discussions for your projects
📈 Trend Tracking: Monitor emerging topics and popular subreddits in the Reddit ecosystem
🎯 Community Research: Identify active communities and assess their engagement
Whether for one-off projects or ongoing monitoring, Reddit Scraper helps transform Reddit data into valuable insights.
Make.com Integration
BrowserAct's Reddit Scraper is now available as a native app on Make.com—add it to your scenarios without API hassle.
✅ Automation-Ready: Integrate with Make, n8n, or others for scheduled monitoring
✅ Rate Limit Handling: Built-in delays to comply with Reddit policies
✅ Multi-Category Tracking: Run instances for different subreddit categories or queries
💡 Use Case Tip: Ideal for competitive analysis, sentiment tracking, and market research with complete discussion metadata
🚀 Quick Start with Make.com: Search for "BrowserAct" in Make.com's app directory and add it directly—no complex setup
Ready to Transform Your Reddit Data Collection?
Stop wasting hours on manual data collection. Start scraping Reddit discussions, trends, and communities in minutes with BrowserAct's AI-powered automation.
Try BrowserAct Free → https://www.browseract.com/
No credit card required. Get started in under 5 minutes.
Popular Use Cases:
- 🛍️ Researchers finding trending discussions
- 💻 Marketers analyzing community sentiment
- 📊 Analysts tracking social trends
- 🏢 Agencies managing client engagement
- 🚀 Developers performing feedback analysis
Start Your Free Trial → https://www.browseract.com/template?page=3
Need Help?
Contact us at:
- 📧 Discord: https://discord.com/invite/UpnCKd7GaU
- 💬 E-mail: service@browseract.com
 What can we do for you